


AI and infrastructure news
Filter by type: All120
- 18 days ago github.com
Kyutai opens the Pocket TTS training stack
On August 25, 2026, Kyutai published the Pocket TTS training stack, including a data pipeline, training recipes, and evaluations for a text-to-speech model designed to run on CPU.
- 18 days ago
 arxiv.org
LoRA+ proposes distinct learning rates for adapter matrices
A September 24, 2026 article examines how using the same learning rate for matrices A and B can hinder feature learning in wide models, and proposes different rates for fine-tuning.
- 18 days ago github.com
MaAI expands training data for its English VAP model
In a post published on September 6, 2026, MaAI says its English VAP model was trained with a larger scale of data. The project describes real-time prediction of conversational cues and head movements.
- 18 days ago arxiv.org
Mol-JEPA explores multimodal data for molecular models
A post published on August 25, 2026 reports that Mol-JEPA learns from molecular structures, cell phenotypes and binding affinities, with out-of-distribution gains on small ADME datasets.
- 18 days ago x.com
NoRA proposes normalizing A at LoRA initialization
A post published on September 2, 2026 describes an initialization that normalizes LoRA's A columns and reports higher average results than several adaptation methods in SFT and RLVR.
- 18 days ago books.vizuara.ai
What pretraining a MoE model demands in practice
Published on August 20, 2026, the account documents an attempt to pretrain a 1.02-billion-parameter MoE model on an H200, covering its data pipeline, failures, and throughput tuning.
- 18 days ago huggingface.co
onPanda enables token annotation and model inspection
Published on September 22, 2026, the onPanda repository presents an open-source tool for LLM data annotation and model inspection.
- 18 days ago huggingface.co
OPD with one query: what the paper proposes
Dated September 29, 2026, the paper tests on-policy distillation with a single training query across math, coding, instruction following, and agentic tool use.
- 18 days ago arxiv.org
ORPO combines SFT and preference alignment in one stage
Published on September 19, 2026, the paper introduces ORPO, a method that combines supervised fine-tuning and preference optimization without a reference model.
- 18 days ago x.com
Ostris AI Toolkit adds LoRA training for MiniMax H3
On August 3, 2026, the Ostris AI Toolkit repository announced LoRA training support for MiniMax H3, limited to text-to-video and image-to-video workflows, using quantized Comfy weights.
- 18 days ago arxiv.org
Paper reports gains from redistributing capacity across layers
Research on language models reports that cosine-shaped capacity allocation improved perplexity without increasing parameters or FLOPs.
- 18 days ago x.com
Model pruning uses effective sample size to select components
A post published on July 1, 2026 presents Effective Model Pruning, a method that uses effective sample size to calculate how many components to retain in neural networks and language models.
- 18 days ago kawine.github.io
Post-training and real-world model adaptation
Slides from an introductory lecture, published August 21, 2026, present post-training methods and adaptation questions for agents in changing environments.
PostTrainBench highlights model performance and reliability
On June 25, 2026, a post about PostTrainBench reported close ranking scores and zero failed runs in 84 attempts for GLM 5.2.
- 18 days ago arxiv.org
PPO and GRPO: choices for long-horizon training
A post published on June 21, 2026 discusses GRPO’s infrastructure constraints and the declining effect of group-based variance reduction on long sequences, compared with PPO.
- 18 days ago alphaxiv.org
Projection Sampling adapts demonstrations for SFT
A paper published on October 4, 2026 presents a way to rewrite expert demonstrations as correct task trajectories that are more likely under the target model, then use them in standard supervised fine-tuning.
- 18 days ago arxiv.org
Pruning or training small LLMs from scratch?
The paper compares six pruning methods for Llama-3.1-8B with training from scratch under two token-budget scenarios; the advantage depends on how the budget is counted.
- 18 days ago arxiv.org
QLoRA: fine-tuning a 65-billion-parameter model on a 48 GB GPU
A paper dated September 20, 2026, reports fine-tuning a 65-billion-parameter model on a single 48 GB GPU with QLoRA, preserving performance on 16-bit fine-tuning tasks.
- 18 days ago x.com
Local branching to scale LLM inference
A paper published on July 5, 2026 proposes generating and selecting token branches during inference; the post reports better mathematical reasoning than three comparison approaches.
- 18 days ago doi.org
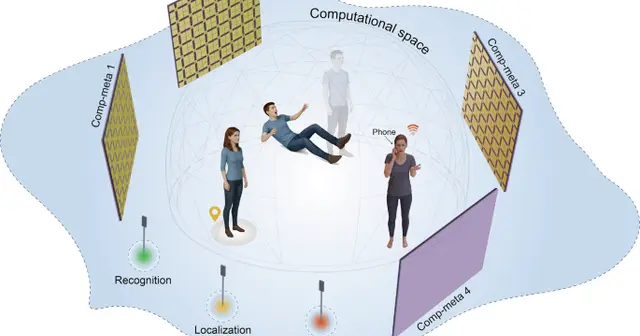
Physical neural network of metasurfaces trained without digital models
The Nature Communications paper describes a physical neural network built from four programmable metasurfaces that learns through electromagnetic interactions to focus waves, recognize objects and perform localization, without digital models.
- 18 days ago arxiv.org
ResidencyRL explores clinical training through simulated consultations
Published on August 10, 2026, the article describes reinforcement learning in simulated clinical environments to train reasoning beyond static medical benchmarks.
- 18 days ago zhihu.com
Long-horizon RL may favor PPO
A Zhihu post published on June 24, 2026, argues that long, noisy agentic rollouts may make credit assignment harder for GRPO and make PPO's value model useful.
RL for beneficial behavior across domains
In a post published on June 18, 2026, OpenAI reports that behavior-focused reinforcement learning improved alignment across domains and resisted adversarial pressure.
- 18 days ago x.com
Post-training RL with fewer parameters changed
A post published on July 5, 2026 describes an approach that reinforces high-contribution intermediate layers during post-training RL. It may match or outperform RL across all parameters while changing fewer parameters.
- 18 days ago arxiv.org
RLSD adjusts RLVR updates at the token level
A paper published on July 11, 2026 presents a training method that combines environmental rewards with self-distillation. Across five multimodal reasoning benchmarks, it reports higher average accuracy than the base model and GRPO.
- 18 days ago arxiv.org
RoLA proposes low-rank linear attention for Diffusion Transformers
Published on September 15, 2026, the paper presents RoLA, a method combining low-rank linear attention and rotary position encoding to address scaling bottlenecks in Diffusion Transformers.
- 18 days ago x.com
Sampling for SFT: evaluating post-training
A post published on October 2, 2026 presents a method that adds sampling to the post-training stack and claims it may improve generalization and reduce forgetting in some cases.
- 18 days ago alphaxiv.org
Self-play for pretraining models without natural data
A paper published on September 26, 2026 examines pretraining with program-generated byte sequences and reports transfer to unseen modalities and tasks.
- 18 days ago x.com
Data-free self-play: how to evaluate the approach
A paper dated September 25, 2026 explores self-play pretraining without real data and reports predictable reductions in zero-shot validation loss across several modalities.
- 18 days ago arxiv.org
SFT in LLMs: tracking effects and deciding when to stop
A paper published on June 15, 2026 examines why supervised fine-tuning can benefit smaller models yet have inconsistent or harmful effects in LLMs.
- 18 days ago x.com
JEPA SIGReg: concepts and a training loop
Published on July 24, 2026, the guide covers complex numbers, Euler’s formula, the Cramér–Wold theorem, and a functional training loop related to JEPA SIGReg.
- 18 days ago x.com
SIGReg and pairwise repulsion in JEPA training
A post dated September 28, 2026 describes how the SIGReg regularizer approximates a sliced MMD and introduces repulsion between batch samples during JEPA training.
- 18 days ago github.com
slime: an open framework for LLM post-training
Published on June 19, 2026, the THUDM repository presents a framework for post-training language models with reinforcement learning and scaling.
- 18 days ago arxiv.org
TAPA proposes token-aware phase attention for long contexts
Published on June 26, 2026, the paper presents Token-Aware Phase Attention (TAPA), a positional encoding method with a trainable phase function, and compares it with RoPE in long contexts.
- 18 days ago huggingface.co
The Stack v3: a code dataset with 5 trillion tokens
The Stack v3 contains about 5 trillion tokens of code across 713 filtered languages and 224 million repositories, based on GitHub collection completed by August 2025.
- 18 days ago x.com
TinyLoRA tests reinforcement fine-tuning with 13 parameters
A post published on September 17, 2026 describes a technique using 13 trainable parameters and reports gains on three mathematics benchmarks.
- 18 days ago x.com
TR-DPO limits deviations in DPO training
A September 21, 2026 publication describes adding a KL-divergence penalty to the DPO loss to limit deviation from the reference model and stabilize offline training.
- 18 days ago github.com
Online DSpark training in Speculators
On July 2, 2026, the Speculators repository presented a shell script for online DSpark training with Qwen3 0.6B and ShareGPT, in the context of speculative decoding for vLLM.
- 18 days ago arxiv.org
Turn-PPO and training agents across multiple turns
An article published on June 21, 2026 presents Turn-PPO, a per-turn advantage estimation method for using PPO to reinforce-train agentic LLMs, and examines GRPO limitations in long-horizon tasks.
- 18 days ago arxiv.org
Vocabulary Transfer for improved sparse retrieval
A paper dated July 2, 2026, attributes advanced encoders’ weaker learned sparse retrieval performance to tokenizer vocabulary incompatibilities and proposes Vocabulary Transfer.
Let's assess your project

I reply with scope and a proposal.