


AI and infrastructure news
Filter by type: Paper273
- 18 days ago cdrdv2-public.intel.com
Intel updates the AVX10.2 specification to version 6.0
In a post published on March 11, 2026, Intel announced version 6.0 of the AVX10.2 specification and the renaming of AVX10_VNNI_INT to AVX10_V1_AUX.
- 18 days ago cdrdv2-public.intel.com
Intel publishes HPC tuning guide for Xeon 6
On December 29, 2025, Intel released version 1.2a of its tuning and optimization guide for high-performance computing applications on Xeon 6 systems.
- 18 days ago arxiv.org
Interleaved Head Attention explores communication between heads
A post published on April 11, 2026, explores communication between attention heads within a layer, focusing on reasoning with Interleaved Head Attention.
- 18 days ago ieeexplore.ieee.org
Gradient inversion in Federated Learning: risks and defenses
Published on January 16, 2026, the post presents a study of gradient inversion attacks in Federated Learning. It says the most practical attack method remains unreliable and that the work proposes a three-stage defense.
- 18 days ago
 arxiv.org
JustRL tests simple RL on 1.5B reasoning models
Published on January 4, 2026, the paper describes single-stage training with fixed hyperparameters and reports average accuracies of 54.9% and 64.3% across two 1.5B reasoning models.
- 18 days ago arxiv.org
KArAt proposes learnable attention without fixed softmax
Published on October 27, 2025, the paper presents KArAt, a learnable alternative to softmax attention. It reports mixed results in vision transformers and low-rank variants intended to reduce memory use.
- 18 days ago arxiv.org
Kascade reduces attention computation in long contexts
Published on February 18, 2026, the article describes a technique that reuses attention results across Transformer layers to reduce inference work without retraining the model or changing its weights.
- 18 days ago arxiv.org
LightRetriever cuts the cost of LLM-based retrieval
A post published on March 5, 2026 reports query encoding 1,000× faster and 10× higher throughput with LightRetriever, while retaining 95% of benchmark performance.
- 18 days ago github.com
Geometric limits on compression in RAG
A NeurIPS 2026 paper studies compression in RAG through embedding geometry and says a spectral quantity defines a minimum limit for compression.
- 18 days ago arxiv.org
LoPA uses lookahead to accelerate diffusion model inference
Published on January 11, 2026, the text presents LoPA, a training-free algorithm that uses lookahead to select token-filling orders in diffusion language models.
- 18 days ago arxiv.org
LoRA as knowledge memory: limits to evaluate
Published on March 3, 2026, the paper analyzes LoRA adapters for updating language-model knowledge and examines capacity limits, modular scaling, and interference when merging modules.
- 18 days ago arxiv.org
Mamba-3 proposes fixed-state sequence modeling
Published on May 7, 2026, the post describes a non-Transformer language architecture that compresses context into a fixed-size state and claims decoding time constant with respect to sequence length.
- 18 days ago arxiv.org
MegaRAG proposes multimodal graphs for RAG
Published on December 25, 2025, the paper describes a method that automatically builds knowledge graphs from visual documents to support retrieval and cross-modal reasoning.
- 18 days ago arxiv.org
Megatron-LM splits models across GPUs for training
A 2019 NVIDIA paper describes using model parallelism to train language models with billions of parameters by distributing weights across GPUs when they do not fit on one.
- 18 days ago people.freebsd.org
Memory and performance: turning knowledge into diagnosis
Published on March 29, 2026, Ulrich Drepper’s article discusses memory for programmers and offers context for engineers investigating memory behavior and software performance.
Layered memory for long-horizon research agents
A post dated April 19, 2026 describes ML-Master 2.0’s Hierarchical Cognitive Caching, with short-, medium-, and long-term memory, and reports a 56.44% medal rate on MLE-Bench after a 24-hour run.
MemRL learns to prioritize agent memories at runtime
Published on January 13, 2026, the description presents MemRL, an approach that learns the utility of episodic memories without changing language-model weights.
- 18 days ago nature.com
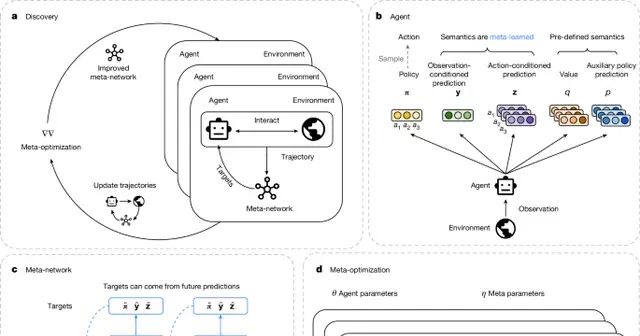
Meta-learning proposes update rules for reinforcement learning
Published on October 24, 2025, the article presents DiscoRL, a method that learns reinforcement learning update rules across agents and environments and reports leading results on benchmarks including Atari and ProcGen.
- 18 days ago arxiv.org
MoDA connects attention across LLM layers
Published on April 19, 2026, the paper presents MoDA, a mechanism combining key-value pairs from the current layer with information from earlier layers.
- 18 days ago arxiv.org
Masked diffusion models and token order
An ICML 2025 paper examines why masked diffusion models underperform on generation benchmarks and identifies challenges in training with subsets of tokens.
- 18 days ago arxiv.org
Ouroboros tests input-conditioned LoRA in recursive transformers
Published on April 25, 2026, the paper explores a compact controller that modulates a shared transformer block at each step. On Qwen2.5-3B, it reports lower training loss than a 17-layer baseline, with gains observed in-distribution.
PARE-Bench tests proactive agents in stateful apps
Published on April 25, 2026, the paper presents 143 tasks for evaluating agents that infer goals, choose when to intervene, and coordinate actions across apps.
- 18 days ago arxiv.org
RAG: More documents may reduce reliance on larger LLMs
A CMU researchers’ paper, dated January 14, 2026, evaluates expanding the retrieval corpus as an alternative to scaling up the model. According to the post, a medium-sized model with more documents may match a larger model with a smaller corpus.
ReCode combines planning and action in LLM agents
Published on December 13, 2025, the article presents ReCode, a recursive code-generation approach that lets LLM agents switch between strategic planning and detailed actions.
- 18 days ago arxiv.org
KL regularization in RL may defy intuitions about diversity
Published on October 24, 2025, the article examines reverse KL and forward KL regularization in reinforcement learning and finds that the usual distinction between mode-seeking and mass-covering does not necessarily apply.
- 18 days ago arxiv.org
Multimodal RL: stability with a single rollout
A December 23, 2025 publication reports that advantage shaping with an entropy bonus stabilized a single-rollout approach to multimodal reinforcement learning.
- 18 days ago arxiv.org
RobustMerge combines specialist MLLMs without retraining
Published on November 15, 2025, the post describes a method for combining multimodal models fine-tuned for specific tasks into a multitask model without further training.
- 18 days ago arxiv.org
RouteRAG adapts text and graph searches during reasoning
Published on December 15, 2025, the material describes a RAG framework using reinforcement learning to choose searches and penalize unnecessary retrieval.
- 18 days ago arxiv.org
SA-RAG explores graph activation for evidence retrieval
Published on December 20, 2025, the paper presents SA-RAG, which propagates activation across weighted knowledge-graph connections to retrieve documents linked to relevant entities.
- 18 days ago arxiv.org
SAR as a reward signal for LLMs
A publication dated January 16, 2026 presents Self-Aligned Reward, compatible with PPO and GRPO, to pursue better reasoning with fewer tokens.
- 18 days ago arxiv.org
Lower SFT learning rates may preserve general capabilities
A study published on October 23, 2025, reports that lower learning rates may retain LLMs’ general capabilities while maintaining specialized performance; it also presents the TALR method.
- 18 days ago arxiv.org
SFT or reinforcement fine-tuning for continual post-training?
An article published on January 11, 2026 compares SFT and reinforcement fine-tuning in continual post-training of foundation models. Its title claims reinforcement fine-tuning naturally mitigates forgetting.
- 18 days ago arxiv.org
SHINE generates LoRA adapters from context in one pass
Published on April 6, 2026, the paper presents a hypernetwork that maps contexts to LoRA adapters while reusing a language model's frozen parameters.
- 18 days ago tugraz.elsevierpure.com
Browser SSD side channel may reveal user activity
An article published on May 29, 2026 reports that SSD latency measurements through the browser's Origin Private File System can identify visited sites and detect launched desktop applications.
- 18 days ago arxiv.org
Skill-RAG adapts retrieval to detected knowledge gaps
Published on April 20, 2026, the paper presents a method that detects potential knowledge gaps and routes queries to specialized retrieval strategies. It evaluates the approach on HotpotQA, Natural Questions, and TriviaQA.
- 18 days ago arxiv.org
Socratic-Zero uses agents to generate reasoning curricula
Published on October 28, 2025, the paper presents a method for generating reasoning data without human labels and reports results across seven mathematical reasoning benchmarks.
StructMem proposes temporal hierarchical memory for agents
Published on April 24, 2026, the StructMem paper proposes hierarchical memory for long-term conversational agents, with event relationships intended to support temporal reasoning and multi-hop questions.
TACO proposes context compression for terminal agents
The paper describes a framework that learns context-compression rules from terminal-agent interactions and reports tests on three benchmarks.
- 18 days ago arxiv.org
Tensor Product Attention proposes reducing KV cache memory
Published on October 27, 2025, the article presents an attention technique using contextual low-rank components to reduce KV cache memory use during inference.
- 18 days ago huggingface.co
Expert trajectories for training language models
On October 31, 2025, a publication presented a method that uses expert trajectories to teach small language models to reason about difficult problems.
Let's assess your project

I reply with scope and a proposal.