


AI and infrastructure news
Filter by type: Paper273
- 19 days ago arxiv.org
FIBER proposes separating GPU register ownership from execution
Published on August 21, 2026, the article presents a GPU architecture that decouples register ownership from parallel execution instances.
- 19 days ago arxiv.org
Context filtering for attention on constrained hardware
A SAS article published on September 16, 2026 describes an end-to-end trained selector inside Softmax to filter context in attention mechanisms aimed at hardware with limited computing resources.
- 19 days ago
 arxiv.org
FlashAttention-3: optimizing attention on Hopper GPUs
Published on September 24, 2026, the paper presents asynchronous execution and low-precision techniques to accelerate attention on Hopper GPUs, focusing on memory traffic and hardware utilization.
- 19 days ago arxiv.org
FlowTracer tracks influential tokens in LLM reasoning
Published on July 4, 2026, the article presents a method that uses attention to trace information propagation and direct credit assignment in reinforcement learning.
- 19 days ago arxiv.org
Gated Linear Attention: linear attention with gates
Published on September 20, 2026, the paper presents a transformer formulation with linear attention and data-dependent gates, also expressible as an RNN with matrix-valued hidden states.
Git as shared memory for research agents
A post published on September 17, 2026 describes agents recording verifiable contributions in a searchable Git history to share results and reduce repeated experiments.
- 19 days ago arxiv.org
GOAT proposes trainable priors for attention
Published on October 3, 2026, the paper frames standard attention as an entropic optimal transport problem with an implicit uniform prior and presents GOAT, which uses a continuous, trainable prior.
- 19 days ago arxiv.org
GPU-Tile-Sim proposes tile-based GPU simulation for LLM co-design
Published on July 14, 2026, the paper proposes a tile-based GPU simulation framework to support hardware and software co-design for LLMs.
- 19 days ago arxiv.org
BF16 gradients rise late in training
A paper reports a 1,000-fold increase in gradient norm after 25 billion tokens in a transformer trained with FlashAttention-3 in BF16.
- 19 days ago arxiv.org
GraphRAG for questions across document collections
A paper published on September 24, 2026 presents an approach to answering global questions about a corpus, which standard retrieval of individual passages may not handle well.
HarnessBank: evolving agent harnesses
An article published on July 17, 2026 describes a method for improving agents by changing prompts, tools, and control loops around the model.
HASTE shows how to organize skills for ML agents
The material on HASTE reports that, across eight competitions, hierarchical skill loading achieved a 100% medal rate, compared with 62.5% for flat loading.
- 19 days ago arxiv.org
HiLS learns chunk selection for sparse attention
Published on July 7, 2026, the paper presents HiLS, an approach that learns chunk selection for sparse attention using the language-modeling loss.
- 19 days ago arxiv.org
HOLA pairs linear attention with an exact, bounded KV cache
Published on July 3, 2026, the paper presents HOLA, an architecture combining recurrent state and a bounded key-value cache, with reported gains in perplexity and long-range recall.
- 19 days ago arxiv.org
HOLA combines recurrent state and a limited cache for long contexts
A post dated July 6, 2026 describes HOLA, which uses recurrent state and a small KV cache for exact memory. The method reduces perplexity by 16.1% and maintains robust retrieval at 32k tokens.
- 19 days ago arxiv.org
HySparse2 cuts long-context costs through KV reuse
Published on September 23, 2026, the post describes two levels of KV sharing to reduce prefill FLOPs and cache size, with better retrieval scores than MiMo-V2.6's Hybrid SWA at a context length of 1 million tokens.
- 19 days ago arxiv.org
iLLaDA: masked diffusion in an 8B model
A description published on June 25, 2026 presents iLLaDA, an 8B masked-diffusion language model trained from scratch with fully bidirectional attention.
- 19 days ago arxiv.org
Privileged information may affect long reasoning in models
An article dated July 7, 2026 reports degradation in long reasoning trajectories after self-distillation with privileged information, across five models evaluated on AIME.
- 19 days ago cdrdv2-public.intel.com
Intel updates paper on memory protections
On July 1, 2026, Intel updated its technical paper on memory protections in Intel architecture for confidential computing, document 869103.
- 19 days ago arxiv.org
Interpretability beyond human concepts
Published on September 22, 2026, the paper investigates whether language models use internal representations that do not map adequately to familiar human concepts.
IO Factory and the detection of adaptive influence campaigns
An article published on August 12, 2026 describes an AI framework that simulates coordinated, adaptive campaigns and highlights the challenge of detecting this activity.
- 19 days ago arxiv.org
Jamba combines Transformer, Mamba and MoE
The paper, published on September 20, 2026, describes a hybrid architecture that interleaves Transformer and Mamba blocks and uses mixture-of-experts in some layers.
JAZ explores agents built around one code primitive
Published on September 26, 2026, the post describes the JAZ framework and reports results on StuLife and AppWorld, with lower costs than the compared approaches.
- 19 days ago arxiv.org
JEPA-Anything explores predictive learning across seven domains
The post, published on October 6, 2026, presents JEPA-Anything as a domain-agnostic world-modeling framework based on orthogonal predictive factorization.
- 19 days ago arxiv.org
JetSpec speeds up speculative decoding with parallel draft trees
A post published on July 7, 2026 describes JetSpec, which uses a single forward pass to generate coherent draft trees and reports speedups of up to 9.64× on MATH-500 and 4.58× in open-ended conversations.
JIT-Agent adapts agent harnesses to each task
The article on JIT-Agent describes on-demand synthesis and evolution of harnesses for LLM-based agents, using modules for memory, planning, actions, and tools. Published August 27, 2026.
- 19 days ago arxiv.org
KATA explores spherical packing for recall in linear attention
A paper published on September 16, 2026 presents KATA, a geometric approach that formulates associative recall in linear attention as a spherical packing problem.
- 19 days ago arxiv.org
KbSD proposes calibrating search decisions in agents
Published on June 30, 2026, the paper describes a self-distillation method to guide search agents in choosing between model memory, retrieved evidence, or abstention.
- 19 days ago arxiv.org
KITE expands Transformers without increasing KV computation
Published on September 29, 2026, the material describes KITE, an approach that expands decoder components by reusing a KV cache generated by a smaller prefiller.
- 19 days ago aclanthology.org
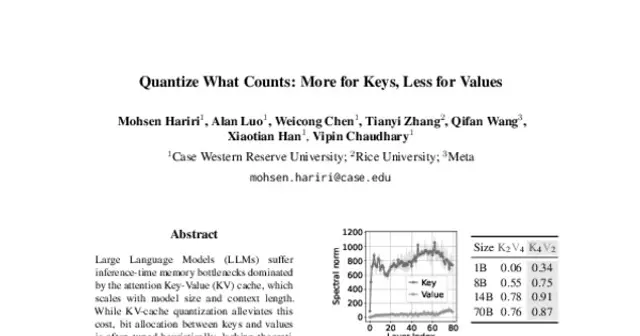
KV cache: more bits for keys than values
An ACL 2026 paper examines KV cache compression and reports that using 4 bits for keys and 2 for values can work well, while reversing that allocation substantially degrades accuracy.
- 19 days ago arxiv.org
LED explores intermediate layers in reasoning models
An article published on July 10, 2026, reports that Latent Exploration Decoding uses intermediate-layer distributions to expand exploration without additional training.
- 19 days ago arxiv.org
LENS combines image reasoning and segmentation with RL
The article presents LENS, a framework using reinforcement learning to jointly optimize reasoning and text-guided image segmentation.
- 19 days ago arxiv.org
LoopCD uses previous loops in decoding
Published on October 2, 2026, the paper presents LoopCD, a training-free method that uses representations from previous loops to guide token selection in Looped Transformers.
- 19 days ago arxiv.org
Looped flows train recurrent updates with local denoising
A paper published on September 12, 2026 proposes local denoising objectives to train recurrent hidden-state updates, including when backpropagation covers few steps.
- 19 days ago arxiv.org
LoRA+ proposes distinct learning rates for adapter matrices
A September 24, 2026 article examines how using the same learning rate for matrices A and B can hinder feature learning in wide models, and proposes different rates for fine-tuning.
- 19 days ago arxiv.org
Mamba and Transformers: a connection behind the architectures
An article published on September 24, 2026 explores theoretical connections between state-space models such as Mamba and attention variants.
- 19 days ago arxiv.org
MaxSim and the capacity to represent inner products
An article dated July 8, 2026, shows that MaxSim can exactly replicate inner products between nonnegative k-sparse vectors, providing a theoretical basis for late-interaction retrieval systems.
- 19 days ago arxiv.org
Megalodon and long-sequence evaluation
An article published on September 24, 2026 presents an architecture based on Mega, designed for efficient pretraining and inference with unlimited context.
MemoHarness adapts agents using execution history
Published on July 17, 2026, the work presents a method that adjusts six dimensions of an agent harness using prior executions. On a shell-agent benchmark, it scored 0.806, compared with 0.722 for the strongest fixed-harness baseline.
Agent memory with a frozen model
In a post published on August 26, 2026, Recuris describes two memory loops and a fixed meta-agent that proposes repairs based on execution traces, without changing model weights.
Let's assess your project

I reply with scope and a proposal.