


AI and infrastructure news
Filter by type: All66
- 17 days ago x.com
Developing high-performance CUDA matmul kernels
Published on September 29, 2025, the guide covers GPU memory hierarchy, CUDA programming, and PTX/SASS inspection to inform the development of matmul kernels.
- 17 days ago aleksagordic.com
Matrix multiplication kernels on NVIDIA GPUs
An article published on October 1, 2025, on GPU architecture and kernel techniques for accelerating matrix multiplication.
- 17 days ago modal.com
Attention optimization: lessons from FlashAttention-4
In a post published on September 26, 2025, Modal describes reverse-engineering techniques for FlashAttention-4 and attributes a 20% performance gain to them.
Penny and GPU communication: what to monitor
A post dated September 21, 2025, begins a development diary about Penny, a GPU communication library built manually.
- 18 days ago docs.nvidia.com
NVIDIA CUDA guide update calls for a technical review
NVIDIA's publication says the CUDA C++ Programming Guide was updated in June 2026. Companies developing GPU software can review their practices and document the standards used across projects.
- 18 days ago tcgen05.mma
Blackwell Tensor Memory and matmul accumulation
The post describes how Blackwell's Tensor Memory, a separate 256 KB space per SM, stores Tensor Core results and reduces, according to the author, the issue of a matmul from 128 threads to one.
- 18 days ago blog.mlc.ai
How to evaluate agent-driven GPU kernel optimization
TIRx Harness combines compiler analysis, a kernel catalog, hardware specifications and remote GPU evaluation to explore, debug and optimize kernels with agents.
How a memory read moves through the RTX 4090
An article dated August 13, 2026 traces an LDG.E SASS instruction through the RTX 4090’s hardware units and memory hierarchy, including details explored through reverse engineering.
- 18 days ago x.com
CUDA C++: GPU execution, memory and correctness
Published on September 19, 2026, NVIDIA's CUDA C++ programming guide covers kernels, threads, memory, synchronization, errors, and validating GPU results against the CPU.
- 18 days ago fergusfinn.com
From nvcc to warps: how a CUDA kernel runs
Published on July 8, 2026, the article follows a vector-addition kernel from compilation with nvcc to execution by GPU warps.
- 18 days ago arxiv.org
FIBER proposes separating GPU register ownership from execution
Published on August 21, 2026, the article presents a GPU architecture that decouples register ownership from parallel execution instances.
- 18 days ago x.com
Fork Enables PCIe P2P on GeForce
A post published on August 27, 2026 reports a graphics-driver change enabling peer-to-peer PCIe transfers on GeForce cards while optimizing GPU serving.
- 18 days ago x.com
Two-core GPU on a $30 FPGA: what to assess
Published on July 9, 2026, the article describes a two-core GPU implemented on a $30 FPGA, running AI model inference at 81 MHz.
- 18 days ago arxiv.org
GPU-Tile-Sim proposes tile-based GPU simulation for LLM co-design
Published on July 14, 2026, the paper proposes a tile-based GPU simulation framework to support hardware and software co-design for LLMs.
- 18 days ago wheels.astral.sh
GPU indexes expand PyTorch and Python support
An Astral post published on October 5, 2026, reports support for PyTorch 2.13 and 2.14 and Python 3.15, with GPU wheels for packages including FlashAttention and DeepSpeed.
- 18 days ago x.com
GPU latency hiding: measure before optimizing
A chapter by Vasily Volkov of UC Berkeley, published July 4, 2026, on how GPUs hide latency and architecture concepts related to performance.
- 18 days ago mlc.ai
CMU book covers GPU programming for ML systems
Published on June 23, 2026, the online book draws on a CMU ML Systems course mini-series and covers GPU programming techniques for ML systems.
- 18 days ago vxlang.org
Heterogeneous memory: compiler capacity checks
In a post published on September 28, 2026, Vx describes a machine model based on capacity, connections, and visibility, and reports two capacity errors found on a laptop without a GPU.
- 18 days ago x.com
What happens when a CUDA kernel is launched
A post published on July 11, 2026, about the CPU-to-GPU communication needed to launch a CUDA kernel and the work involved in that operation.
- 18 days ago leetgpu.com
CUDA practice with GPU challenges
In a post published on August 12, 2026, LeetGPU recommends a challenge-based CUDA practice path, from SIMD kernels to shared memory, tiling, and more advanced features.
- 18 days ago x.com
PufferLib 4.0 reports multi-GPU scaling
Published on June 21, 2026, the report on PufferLib 4.0 describes 6.6× scaling across eight GPUs in a worst-case test and throughput above 100 million steps per second on eight RTX 5090 GPUs.
- 18 days ago github.com
auto-gpu-kernel 1.0 repository generates GPU kernels and harnesses
Published on September 15, 2026, the repository presents a system that evolves GPU kernels and harnesses and won the DSA category of an MLSys 2026 FlashInfer contest.
- 18 days ago leimao.github.io
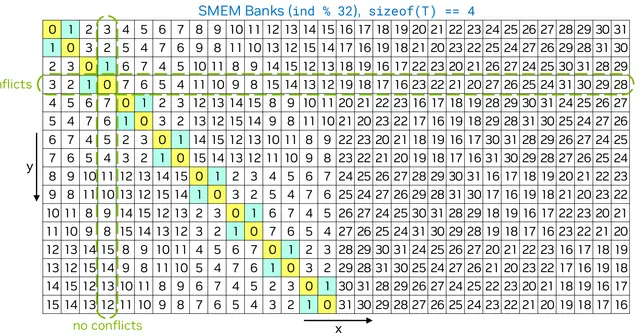
Swizzling to reduce conflicts in CUDA shared memory
A technical article dated August 13, 2026 discusses using swizzling to address bank conflicts in CUDA shared memory, which can affect kernel performance.
- 18 days ago github.com
Symmetric memory may optimize GPU communication
A Machine Learning Engineering Open Book post, published on October 5, 2026, discusses symmetric memory in NCCL and PyTorch and its potential for small and medium payloads and overlapping communication with computation.
- 18 days ago docs.vulkan.org
Vulkan: compute shaders, GPUs and memory models
A tutorial published on July 12, 2026 presents compute shaders, GPU architecture and memory models, concepts that also help explain DirectX 12.
- 18 days ago
 hgpu.org
Xtrace proposes detailed tracing of GPU kernels
A description published on September 27, 2026 presents Xtrace, an intra-kernel tracing approach that inserts probes through binary-level instruction splicing.
Let's assess your project

I reply with scope and a proposal.