


AI and infrastructure news
Filter by type: All85
- 5 days ago x.com
Diffusion text models generate the full output at once: what changes for inference
Post describes diffusion text models that produce the whole response simultaneously, instead of token by token like autoregressive LLMs. According to the author, generation is fast, with a latency and cost profile distinct from standard inference.
- 5 days ago x.com
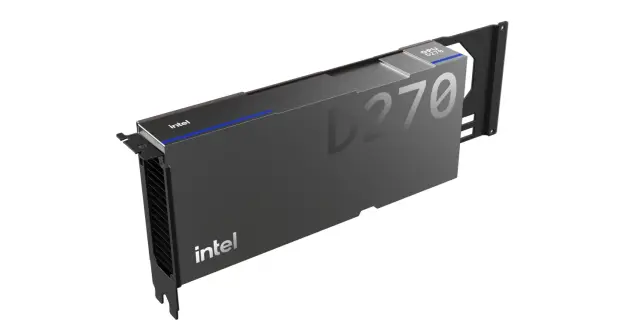
Intel GPU D270 (Crescent Island): inference accelerator with high-capacity LPDDR5X memory
A post describes Intel's D270 GPU (Crescent Island), a PCIe 5.0 card for inference with 32 Xe cores, XMX matrix engines and about 160 GB of LPDDR5X, expandable to 480 GB.
- 6 days ago x.com
Pruning 6 layers of Qwen3-8B-Base with LaCo cuts the model by 16.7%
The post reports removing up to 10 layers from Qwen3-8B-Base using LaCo. With 6 layers removed, the model is 16.7% smaller and, according to the author, keeps 78-94% of its reasoning scores, with a perplexity ratio of 1.68x.
- 12 days ago storagereview.com
Intel GPU D-Series: inference card with up to 480GB LPDDR5X now sampling
Intel has presented the D-Series GPU, with up to 480GB of LPDDR5X, 1.5TB/s and 1.3 PFLOPS in FP8 on a 350W PCIe card now sampling. See what it changes for private inference and cost per token.
- 16 days ago x.com
Samsung opens LittleBit, a method that compresses 13B LLMs to under 1 GB
According to the post, Samsung's LittleBit uses latent factorization and sub-1-bit levels to shrink the weights of 13B LLMs to under 1 GB. Worth evaluating for local deployment.
- 17 days ago x.com
Benchmark reports 2.89× faster TTFT at 64K context
Published on May 9, 2026, the benchmark reports that Luce PFlash achieved 2.89× faster time to first token than Ollama with a 64K context.
- 17 days ago x.com
CLI estimates VRAM before loading models
The do-i-have-the-vram tool estimates the GPU memory needed to load a model without loading it, helping assess whether it fits in available VRAM.
- 17 days ago andrewkchan.dev
How to evaluate and optimize LLM inference in a company
Andrew Chan’s article, published on March 1, 2026, covers fast LLM inference from scratch as a practical starting point for engineers.
- 17 days ago turingpost.com
How to compare tools for running foundation models
A Turing Post article published on May 17, 2026, surveys 13 open-source tools for deploying, serving, and running models, from local use to production inference.
- 17 days ago x.com
How to compare MTP inference on older GPUs
A May 16, 2026 publication reports llama.cpp throughput benchmarks with MTP for Qwen 3.6 models on three GTX 1080 Ti GPUs and describes a setup that can inform internal testing.
- 17 days ago lmsys.org
Optimizing Qwen3 latency on AMD GPUs
An article on the LMSYS blog, published on February 13, 2026, discusses latency optimization for Qwen3 and Qwen3-VL on AMD MI300X GPUs.
- 17 days ago x.com
DEER proposes diffusion drafts to accelerate LLM inference
A publication dated December 18, 2025 describes DEER, which drafts tokens with diffusion models and verifies them with autoregressive models. The text claims up to 5.54× faster inference without quality loss.
- 17 days ago x.com
DFlash and DDTree run Qwen3.6-27B on one RTX 3090
A post dated April 23, 2026 reports 73 tokens per second with speculative decoding on a single RTX 3090 and identifies architectural compatibility as a factor in running the model.
- 17 days ago github.com
dflash-mlx v0.1.5 expands runtime and serving features
On May 3, 2026, version 0.1.5 added a unified CLI, RAM and SSD caching, prefix matching, and experimental support for long contexts.
- 17 days ago arxiv.org
Fluxion proposes hybrid sparse attention for long-context inference
Published on May 11, 2026, the article presents a hybrid sparse-attention system for long-context inference using CPU–GPU parallelism.
- 17 days ago x.com
DS4 fork enables tensor-parallel inference across multiple machines
Published on June 9, 2026, a fork of the antirez/ds4 repository adds support for combining tensor parallelism with node roles to distribute inference across multiple machines and GPUs.
- 17 days ago x.com
hf-mem estimates memory for new models
A publication dated February 17, 2026 presents a command-line tool for estimating memory requirements as model architectures change.
- 17 days ago openanonymity.ai
Unlinkable inference to protect user identity
In a post published on February 26, 2026, OpenAnonymity describes a layer designed to prevent AI providers from linking inference calls to individual users.
- 17 days ago baseten.co
Production AI inference requires end-to-end engineering
Published on March 3, 2026, Philip Kiely’s book covers the hardware, software, techniques, and infrastructure for production inference systems, focusing mainly on language models with some coverage of diffusion.
- 17 days ago github.com
Running Llama 70B on an RTX 3090 with ntransformer
On February 22, 2026, the ntransformer repository page says its C++/CUDA inference engine runs Llama 70B on an RTX 3090, transferring data from NVMe to the GPU without passing through the CPU.
- 17 days ago x.com
Local inference: performance and power on an RTX 3090
Tests of eight local LLMs on one RTX 3090 compared throughput and energy efficiency at power limits ranging from 100 W to 450 W.
- 17 days ago outcomeschool.com
KV cache: less recomputation in LLM inference
Published on May 9, 2026, the article explains how KV cache reuses previously computed values and why that matters for memory and computation during inference.
- 17 days ago github.com
llama.cpp adds Multi-Token Prediction support
On May 17, 2026, a pull request to the llama.cpp repository added support for MTP heads. The report cites 65 tokens per second for Qwen3.6-27B on an RTX 3090, versus 38 without MTP.
- 17 days ago github.com
llmfit helps assess models for local hardware
The llmfit repository, published on GitHub on February 21, 2026, analyzes local hardware to identify compatible models and estimate inference speed.
- 17 days ago x.com
LMCache reuses KV cache across GPU, CPU and disk
On January 30, 2026, the description of the open-source LMCache project presented an LLM-serving extension that reuses KV states across GPUs, CPUs and local disks, including repeated text chunks beyond prefixes.
- 17 days ago
 arxiv.org
LoPA uses lookahead to accelerate diffusion model inference
Published on January 11, 2026, the text presents LoPA, a training-free algorithm that uses lookahead to select token-filling orders in diffusion language models.
- 17 days ago github.com
Lucebox explores speculative inference on consumer GPUs
Published on May 9, 2026, the post presents Lucebox, a speculative inference server for heterogeneous hardware, and reports that Qwen3.6-27B reaches 120–200 tokens per second on an RTX 3090.
- 17 days ago huggingface.co
Quantized weights offer a basis for evaluating local inference
A repository published on January 3, 2026, contains W4A16 weights for a 185-billion-parameter model, totaling 92 GB. The author says they ran 100 million tokens locally.
- 17 days ago x.com
Post assesses inference on two RTX Pro 6000 GPUs
Published on April 29, 2026, the post claims that a language model's experts are already quantized to 4 bits and could fit on two RTX Pro 6000 GPUs; it points to missing SM120 support in two serving options.
- 17 days ago github.com
Community recipes for serving LLMs on RTX GPUs
Published on May 24, 2026, the repository collects model-independent configurations for serving LLMs on RTX 3090, 4090, and 5090 GPUs, using vLLM, llama.cpp, and ik_llama.
- 17 days ago x.com
RTX 3090: efficiency and throughput in local inference
Tests reported on May 9, 2026 compared a 27-billion-parameter model on an RTX 3090, varying concurrency and power limits.
- 17 days ago x.com
Serving MoE models with AWS EFA
On November 6, 2025, a Perplexity article described kernels for serving MoE models across AWS GPUs using EFA, without GPUDirect Async.
- 17 days ago kaitchup.substack.com
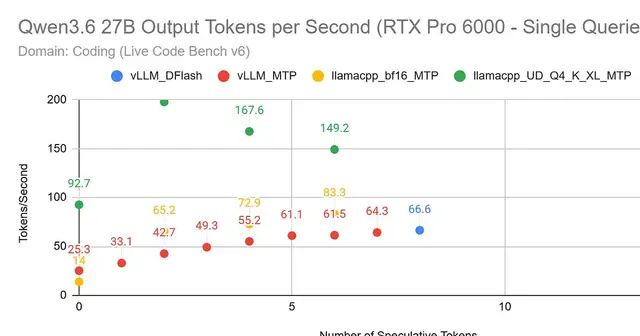
Speculative decoding: performance varies by model
An article published on June 3, 2026 compares DFlash and MTP with vLLM and llama.cpp on math, coding, and chat tasks. Results vary by model and workload.
- 17 days ago x.com
SWAA proposes more efficient inference for long contexts
A post dated December 15, 2025 describes training-free recipes to adapt full-attention language models to linear scaling and recover performance.
- 17 days ago huggingface.co
Techniques for optimizing Transformer inference
A blog post published on December 24, 2025 describes Transformer inference techniques: MXFP4 quantization, tensor and expert parallelism, and dynamic sliding windows.
- 17 days ago github.com
Tencent presents HPC-Ops operators for LLM inference
On January 27, 2026, Tencent presented HPC-Ops, an open-source library of operators for LLM inference, with GPU operations and multinode communication support.
- 17 days ago lightseek.org
TokenSpeed highlights inference optimizations for agents
Published on May 24, 2026, the text describes an inference engine for agentic workloads, with compiler-supported parallelism, a high-performance scheduler, constrained reuse of KV resources, and pluggable kernels for heterogeneous accelerators.
- 17 days ago
 unsloth.ai
Tool calling with local models: from guide to application
Published on February 5, 2026, Unsloth’s guide presents examples of tool calls with local open models, including Python, terminal commands, and mathematics.
- 17 days ago github.com
Training neural networks on the Neural Engine: evaluating the ANE repository
Published on March 2, 2026, the ANE repository describes neural network training using private APIs reverse-engineered from Apple's Neural Engine. Learn how to evaluate this approach before adopting it.
- 17 days ago github.com
Voice agents: parallel models may reduce silence
A contribution to Gradbot, published on June 5, 2026, describes sending a brief response to TTS while another model reasons and calls tools in the background.
Let's assess your project

I reply with scope and a proposal.