


AI and infrastructure news
Filter by type: All85
- 18 days ago github.com
NVIDIA Model Optimizer gathers model compression techniques for inference
NVIDIA published a post on Model Optimizer, a library with quantization, distillation, pruning, neural architecture search and speculative decoding, with exportable checkpoints for vLLM, SGLang, TensorRT-LLM and TensorRT.
- 18 days ago x.com
Concurrent Llama 3.1 8B inference on an RTX 3090
A Backprop post published on August 16, 2024 reports reasonable performance in a benchmark with more than 100 concurrent requests on a single GPU.
- 18 days ago x.com
Layered inference on memory-limited GPUs
On September 25, 2024, the AirLLM publication described inference that loads one Transformer layer at a time from disk, as well as block quantization and compression support.
- 18 days ago
 arxiv.org
InfLLM-V2 switches between dense and sparse attention
Published on October 13, 2025, the paper presents an attention system that switches between dense and sparse modes for short and long sequences.
- 18 days ago x.com
Jamba 1.5: 256K context and inference evaluation
On August 22, 2024, AI21 Labs announced the Jamba 1.5 Mini and Large models, combining Mamba and Joint Attention, with a 256K-token context window and features including ExpertInt8 and JSON output.
- 18 days ago github.com
LLM Compressor brings model compression techniques to vLLM
In a post published on August 16, 2024, Neural Magic introduced a library of compression techniques intended to reduce inference latency while preserving accuracy.
- 18 days ago github.com
Mirage compiles LLMs into persistent megakernels
Published on June 19, 2025, the publication describes a compiler that transforms LLMs into persistent megakernels and claims latency reductions of 1.2 to 6.7 times.
- 18 days ago cnx-software.com
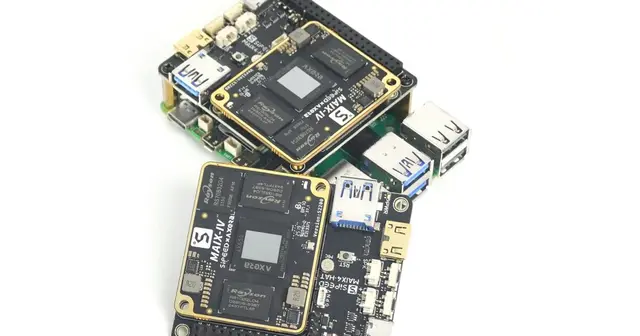
Up to 72 TOPS of NPU capacity on Raspberry Pi 5
In a publication dated August 11, 2025, Sipeed introduced the Maix4-HAT, with an AXera AX650N NPU, up to 72 TOPS in INT4 or 18 TOPS in INT8, and 8 GB of LPDDR4x RAM for edge Transformer inference.
- 18 days ago x.com
PHLoRA extracts LoRA adapters from fine-tuned models
Published on September 17, 2025, the post describes a method for extracting low-rank adapters from fine-tuned checkpoints without training data or gradients.
- 18 days ago arxiv.org
Router-R1 explores reinforcement learning to route LLMs
Published on October 18, 2025, the text presents Router-R1, which alternates between reasoning and calls to multiple models and reports evaluations on seven question-answering benchmarks.
- 18 days ago x.com
Inference throughput: SGLang and vLLM on A6000 GPUs
A post published on August 4, 2024 reports higher throughput with SGLang than with vLLM on four A6000 GPUs, but similar performance with smaller batches.
- 18 days ago pytorch.org
Torchchat brings local LLM inference to different devices
Published on July 30, 2024, the PyTorch post presents a library for running Llama 3, 3.1, and other LLMs locally on laptops, desktops, and mobile devices.
- 19 days ago x.com
BITCOS reduces storage for ternary LLMs
In a post published on September 20, 2026, Intel describes BITCOS, a method that stores exact ternary LLM weights at 1.485 bits per weight and reports decode throughput gains.
- 19 days ago youtube.com
Cache and attention: inference optimization
A post dated October 1, 2026 reports attention techniques and reduced KV cache in a language model, with potential implications for inference costs.
- 19 days ago arxiv.org
Test-time training layers for sequence modeling
A paper published on September 24, 2026 presents sequence-modeling layers with linear complexity and hidden states updated through self-supervised learning.
- 19 days ago github.com
Colibri streams MoE experts from disk for local inference
A pure-C inference engine loads experts from mixture-of-experts models from disk, offering an approach to evaluate local execution on hardware with limited memory.
- 19 days ago x.com
How to assess KV cache reductions
A post reports an alleged reduction in KV cache use from 389,000 to 890 bytes per token over three years. The claim points to an opportunity to measure memory and cost in long-context systems.
- 19 days ago x.com
How vLLM schedules requests and allocates the KV cache
The September 26, 2026 article traces a request through vLLM and explains per-iteration scheduling and KV cache block allocation.
- 19 days ago github.com
Reproducing multi-GPU serving and thermal profiling
A GitHub repository published on July 30, 2026 presents a reproducible GLM-5.2 EXL3 MTP3 serving configuration and thermal profile for four RTX PRO 6000 Blackwell GPUs.
- 19 days ago github.com
Model communication on Huawei Ascend NPUs
The publication, dated September 30, 2026, describes a high-performance communication library for machine learning training and inference on Huawei Ascend NPUs.
- 19 days ago github.com
Inference configuration across two DGX Sparks
A pull request dated July 31, 2026 updates the default checkpoint and installs the encoder on both ranks in a two-DGX-Spark configuration.
- 19 days ago crusoe.ai
Crusoe reports inference results on 512 AMD MI355X GPUs
In a September 16, 2026 publication, Crusoe reports MLPerf Inference v6.1 results: 5.75 million tokens per second on gpt-oss-120b and linear scaling without InfiniBand.
- 19 days ago arxiv.org
Dual-Cache: sharing context across LLMs
A paper published on September 26, 2026 presents a latent protocol for transferring information across heterogeneous models by translating KV caches and adding joint mixing between layers.
- 19 days ago github.com
Silent failures in LLM serving: a practical diagnosis
Published on July 28, 2026, the GitHub repository catalogs LLM serving failures, their symptoms, mechanisms, checks, and fixes.
- 19 days ago platform.claude.com
Inference hooks can block prompts before execution
Material dated August 11, 2026 describes hooks that send prompts to an organization’s safety server, which allows or denies them before inference.
- 19 days ago github.com
LLM inference with limited VRAM
A post dated July 17, 2026 describes a framework for heterogeneous inference and fine-tuning, distributing experts across GPU and CPU.
- 19 days ago arxiv.org
JetSpec speeds up speculative decoding with parallel draft trees
A post published on July 7, 2026 describes JetSpec, which uses a single forward pass to generate coherent draft trees and reports speedups of up to 9.64× on MATH-500 and 4.58× in open-ended conversations.
- 19 days ago aclanthology.org
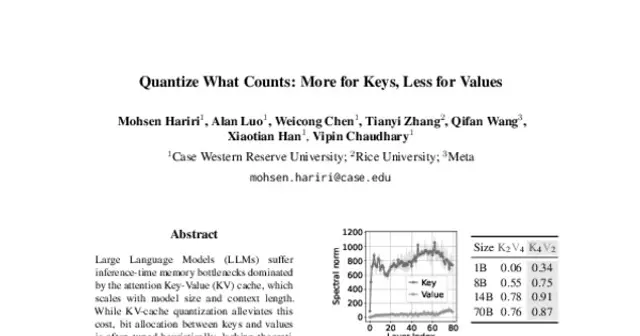
KV cache: more bits for keys than values
An ACL 2026 paper examines KV cache compression and reports that using 4 bits for keys and 2 for values can work well, while reversing that allocation substantially degrades accuracy.
- 19 days ago x.com
KV Cache: Why Queries Are Not Stored
A post dated August 30, 2026 distinguishes the temporary use of queries from the storage of keys and values in the KV cache during inference.
- 19 days ago github.com
Open book covers 12 chapters on AI infrastructure
Published on September 13, 2026, the book covers model architectures, accelerators, inference, and training. Its scope can help companies identify concrete infrastructure challenges.
- 19 days ago arxiv.org
PagedAttention and KV cache management in LLM serving
An article published on September 24, 2026 presents PagedAttention, a virtual-memory-inspired approach to reducing KV cache fragmentation and duplication, which can limit batch size.
- 19 days ago x.com
Post describes calibration-guided low-bit compression of Hy4
A post published on August 29, 2026, says Tencent reduced the Hy4 preview from 1.5 TB to 200 GB by setting precision per layer. It reports results on two benchmarks.
- 19 days ago dstack.ai
dstack Presets proposes portable inference optimization
Published on August 20, 2026, dstack’s announcement presents an open-source toolkit that uses agents to simplify inference optimization and store results in a portable format.
- 19 days ago x.com
Unsloth reports 1-bit quantization reducing model to 217 GB
In a post published on August 28, 2026, Unsloth reports dynamically quantizing GLM-5.3 to 1 bit: 217 GB versus 1.5 TB in BF16, with about 76% top-1 accuracy.
- 19 days ago huggingface.co
Quantization reduces Hy4 Preview to 214 GB
A Tencent post dated September 1, 2026, says Sherry quantization takes Hy4 Preview from 1.5 TB to 214 GB and describes running it on GPUs distributed across multiple machines.
- 19 days ago github.com
Ridgeline: profiling LLM inference with the roofline model
Published on July 8, 2026, the text describes Ridgeline, a PyTorch-based profiler that applies the roofline model to analyze LLM inference workloads.
- 19 days ago arxiv.org
LLM serving: cache and balancing after a year in production
A paper published on August 21, 2026 analyzes a year of production LLM traffic and examines prefix reuse, KV cache locality, and load balancing.
- 19 days ago x.com
Serving models across GPU, RAM and NVMe
A September 12, 2026 post reports running a model on an RTX 5090 with 125.7 GiB of RAM and part of the model file on NVMe.
- 19 days ago arxiv.org
Speculative decoding may reduce inference steps
An article dated September 20, 2026 describes a technique that pairs proposals from an efficient model with parallel verification by a larger model to speed generation without changing the output distribution.
- 19 days ago github.com
Strata brings local MoE inference to GPUs with 8 GB
On October 1, 2026, the Strata repository page described running the 125-billion-parameter Qwen3.8-Flash-Next MoE model on NVIDIA GPUs with at least 8 GB of VRAM.
Let's assess your project

I reply with scope and a proposal.