


AI and infrastructure news
Filter by type: Article16
- 12 days ago storagereview.com
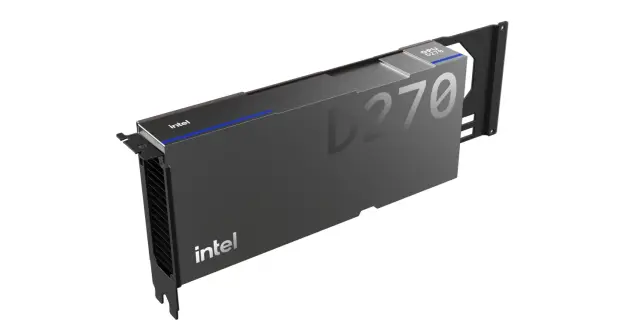
Intel GPU D-Series: inference card with up to 480GB LPDDR5X now sampling
Intel has presented the D-Series GPU, with up to 480GB of LPDDR5X, 1.5TB/s and 1.3 PFLOPS in FP8 on a 350W PCIe card now sampling. See what it changes for private inference and cost per token.
- 17 days ago andrewkchan.dev
How to evaluate and optimize LLM inference in a company
Andrew Chan’s article, published on March 1, 2026, covers fast LLM inference from scratch as a practical starting point for engineers.
- 17 days ago turingpost.com
How to compare tools for running foundation models
A Turing Post article published on May 17, 2026, surveys 13 open-source tools for deploying, serving, and running models, from local use to production inference.
- 17 days ago lmsys.org
Optimizing Qwen3 latency on AMD GPUs
An article on the LMSYS blog, published on February 13, 2026, discusses latency optimization for Qwen3 and Qwen3-VL on AMD MI300X GPUs.
- 17 days ago openanonymity.ai
Unlinkable inference to protect user identity
In a post published on February 26, 2026, OpenAnonymity describes a layer designed to prevent AI providers from linking inference calls to individual users.
- 17 days ago baseten.co
Production AI inference requires end-to-end engineering
Published on March 3, 2026, Philip Kiely’s book covers the hardware, software, techniques, and infrastructure for production inference systems, focusing mainly on language models with some coverage of diffusion.
- 17 days ago outcomeschool.com
KV cache: less recomputation in LLM inference
Published on May 9, 2026, the article explains how KV cache reuses previously computed values and why that matters for memory and computation during inference.
- 17 days ago kaitchup.substack.com
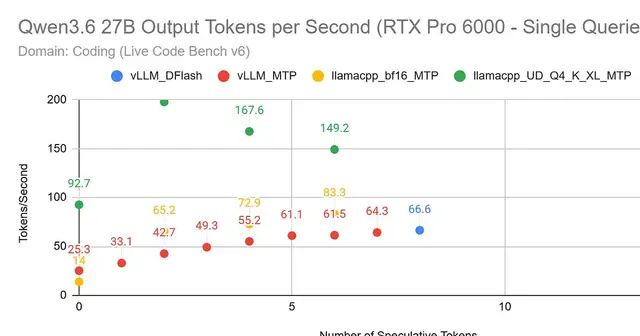
Speculative decoding: performance varies by model
An article published on June 3, 2026 compares DFlash and MTP with vLLM and llama.cpp on math, coding, and chat tasks. Results vary by model and workload.
- 17 days ago huggingface.co
Techniques for optimizing Transformer inference
A blog post published on December 24, 2025 describes Transformer inference techniques: MXFP4 quantization, tensor and expert parallelism, and dynamic sliding windows.
- 17 days ago lightseek.org
TokenSpeed highlights inference optimizations for agents
Published on May 24, 2026, the text describes an inference engine for agentic workloads, with compiler-supported parallelism, a high-performance scheduler, constrained reuse of KV resources, and pluggable kernels for heterogeneous accelerators.
- 17 days ago
 unsloth.ai
Tool calling with local models: from guide to application
Published on February 5, 2026, Unsloth’s guide presents examples of tool calls with local open models, including Python, terminal commands, and mathematics.
- 17 days ago cnx-software.com
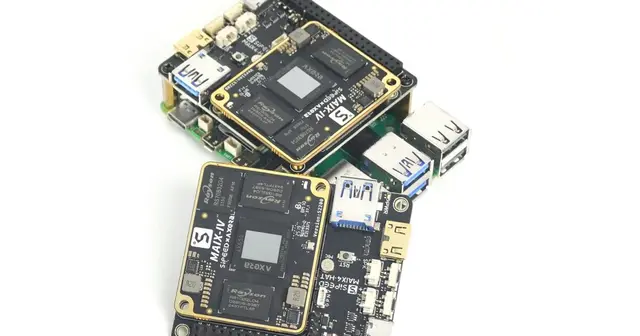
Up to 72 TOPS of NPU capacity on Raspberry Pi 5
In a publication dated August 11, 2025, Sipeed introduced the Maix4-HAT, with an AXera AX650N NPU, up to 72 TOPS in INT4 or 18 TOPS in INT8, and 8 GB of LPDDR4x RAM for edge Transformer inference.
- 17 days ago pytorch.org
Torchchat brings local LLM inference to different devices
Published on July 30, 2024, the PyTorch post presents a library for running Llama 3, 3.1, and other LLMs locally on laptops, desktops, and mobile devices.
- 18 days ago crusoe.ai
Crusoe reports inference results on 512 AMD MI355X GPUs
In a September 16, 2026 publication, Crusoe reports MLPerf Inference v6.1 results: 5.75 million tokens per second on gpt-oss-120b and linear scaling without InfiniBand.
- 18 days ago platform.claude.com
Inference hooks can block prompts before execution
Material dated August 11, 2026 describes hooks that send prompts to an organization’s safety server, which allows or denies them before inference.
- 18 days ago dstack.ai
dstack Presets proposes portable inference optimization
Published on August 20, 2026, dstack’s announcement presents an open-source toolkit that uses agents to simplify inference optimization and store results in a portable format.
Let's assess your project

I reply with scope and a proposal.