


AI and infrastructure news
Filter by type: All83
- 12 days ago
 arxiv.org
QwenGyre: elastic RL for training long-horizon agents
Alibaba Qwen presented QwenGyre, an elastic RL framework that reallocates GPUs between rollout and training and groups branched agent runs into trajectory trees with shared prefixes, with a reported speedup of up to 1.85x over Colocate.
- 17 days ago arxiv.org
Adapting models to Q, a language used in finance
A technical report dated January 9, 2026 presents an open-source approach to adapting language models to Q, a programming language used in quantitative finance.
- 17 days ago arxiv.org
Search agents can check evidence against noise
Published on October 28, 2025, the paper describes an agent that sets search goals and checks whether retrieved evidence meets them, aiming to resist misleading cues.
- 17 days ago x.com
Fine-tuning a 14B code model with SFT and DPO
A January 20, 2026 article describes tuning a 14B model on code conversations and reports figures, costs, and difficulties.
- 17 days ago x.com
Architecture also shapes continual learning
An article published on January 17, 2026 reports that wider networks and less global average pooling may improve retention, while ResNets and WideResNets learn new tasks quickly but forget more.
- 17 days ago arxiv.org
Self-distillation may support continual learning without rewards
A post published on February 16, 2026 describes a self-distillation technique for training models on new tasks without a reward function, with the aim of reducing catastrophic forgetting.
- 17 days ago arxiv.org
BAPO aims to stabilize off-policy training for LLMs
Published on October 23, 2025, the paper presents BAPO, a method using balanced policy optimization and adaptive clipping for partial rollout and experience reuse scenarios.
- 17 days ago arxiv.org
CogRouter adjusts agent reasoning at each step
Published on February 16, 2026, the material describes four cognitive levels for LLM agents and reports 82.3% benchmark success for a 7B model.
- 17 days ago arxiv.org
Stabilizing reinforcement learning with LLMs
A Qwen team article published on December 16, 2025, examines instability in reinforcement learning for language models and highlights differences between training and inference, old and new policies, importance sampling, and routing replay.
- 17 days ago x.com
Measuring scale and cost in RL experiments
A post published on April 18, 2026, compares scaling laws for pre-training and reinforcement learning, highlighting sampling and policy-update costs and evaluation challenges.
- 17 days ago x.com
Progressive distillation for improving VLMs
In a post published on January 4, 2026, the author describes the Masters framework and reports gains on two vision-language models using an approach intended to avoid the computational cost of online RL.
- 17 days ago arxiv.org
EditScore applies reward models to image editing
A post dated October 25, 2025 presents a family of reward models for evaluating and guiding complex image edits, with reported results on EditReward-Bench.
- 17 days ago blog.ml.cmu.edu
Exploration in RL for training LLMs on hard tasks
A CMU blog post published on January 31, 2026 describes three exploration regimes and the risks of stagnation and interference in reinforcement learning.
- 17 days ago
 unsloth.ai
GRPO with 380K context on a 192 GB GPU
On January 15, 2026, Unsloth documentation described long-context GRPO fine-tuning and stated that its batching algorithms enable 380K context for gpt-oss on a 192 GB GPU.
- 17 days ago x.com
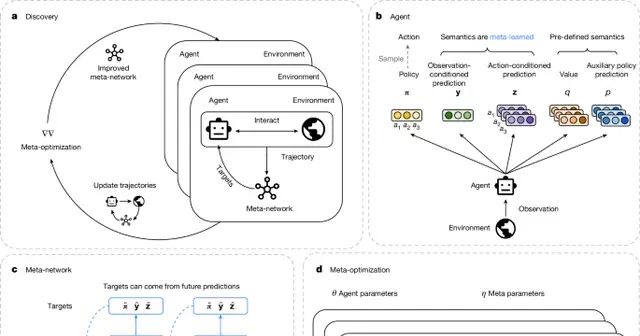
AI may discover reinforcement learning algorithms
A Nature article published on October 28, 2025, reports autonomous discovery of reinforcement learning algorithms and points to a potential new approach for engineers.
- 17 days ago arxiv.org
JustRL tests simple RL on 1.5B reasoning models
Published on January 4, 2026, the paper describes single-stage training with fixed hyperparameters and reports average accuracies of 54.9% and 64.3% across two 1.5B reasoning models.
- 17 days ago x.com
LaSeR explores last-token rewards for LLMs
In a post published on October 19, 2025, Tencent presents LaSeR, a reinforcement learning algorithm that aligns last-token scores with real rewards and uses one extra token inference.
- 17 days ago alphaxiv.org
LoRA for RLVR: averaging specialists beats gating in reported tests
A paper dated January 3, 2026, examines practical PEFT strategies for multi-domain RLVR and reports interference during joint training. In the experiments described, averaging specialist LoRA weights and continuing training outperformed the tested gating method.
- 17 days ago x.com
MaxRL proposes another approach to RL with binary rewards
Published on February 9, 2026, the post describes MaxRL and reports up to 20 times greater test-time efficiency than GRPO.
- 17 days ago nature.com
Meta-learning proposes update rules for reinforcement learning
Published on October 24, 2025, the article presents DiscoRL, a method that learns reinforcement learning update rules across agents and environments and reports leading results on benchmarks including Atari and ProcGen.
- 17 days ago aweers.de
RL methods for reasoning models
An article published on March 16, 2026, surveys reinforcement learning methods used with language models and offers engineering teams a starting point for comparison.
- 17 days ago x.com
Looped models: scaling and practical evaluation
An article dated October 30, 2025 reports training looped language models with 2.6 billion parameters and more than 7 trillion tokens, with performance comparable to models two to three times larger.
- 17 days ago x.com
The Olmo 3 pipeline and training reasoning models
A post published on December 15, 2025 describes SFT with curated traces, followed by DPO and RLVR using group-relative policy optimization.
- 17 days ago github.com
OpenTinker proposes RL infrastructure for foundation models
A description published on January 8, 2026 presents an open-source reinforcement learning platform for agents, separating programming from execution and enabling a transition from training to inference.
- 17 days ago x.com
Long prompts: recursive processing with code
An MIT post published on January 6, 2026 describes models using a Python interface to filter and recursively process segments of long prompts.
- 17 days ago arxiv.org
KL regularization in RL may defy intuitions about diversity
Published on October 24, 2025, the article examines reverse KL and forward KL regularization in reinforcement learning and finds that the usual distinction between mode-seeking and mass-covering does not necessarily apply.
- 17 days ago x.com
Ring-1T: three-stage training for a 1-trillion-parameter MoE
A post published on October 22, 2025 describes Ring-1T, a reasoning MoE model with 1 trillion parameters and about 50 billion active per token, trained in three stages.
RL training systems: rollout challenges and pass@k results
An article published on December 21, 2025, covers rollout challenges in RL training and varied findings on pass@k performance.
- 17 days ago arxiv.org
Multimodal RL: stability with a single rollout
A December 23, 2025 publication reports that advantage shaping with an entropy bonus stabilized a single-rollout approach to multimodal reinforcement learning.
- 17 days ago x.com
Offline RL: Bayesian generalization in models
A post dated January 14, 2026, describes a paper exploring adaptive Bayesian generalization in model-based offline RL, using long-horizon rollouts to reduce conservative constraints.
- 17 days ago
 hgpu.org
Online RL for HPC code generation with real-machine benchmarks
Published on February 15, 2026, the paper describes online reinforcement learning, rewarded by benchmarks on real machines, to improve HPC code generation. Runtime performance of generated code is not guaranteed.
- 17 days ago x.com
RLAC proposes an adversarial critic for open-ended generation
In a post published on November 5, 2025, the RLAC approach reports greater factuality and better code scores, with fewer validation calls, data, and test cases.
- 17 days ago rocm.blogs.amd.com
RLHF on AMD GPUs: deployment with ROCm 7.0
An AMD article published on March 2, 2026 describes using verl for RLHF training on AMD GPUs, with ROCm optimizations and Docker scripts, and presents throughput and convergence results.
- 17 days ago x.com
RLoop alternates exploration and consolidation in RL
A post published on November 7, 2025 describes an iterative policy initialization strategy and reports gains on two evaluation metrics.
- 17 days ago arxiv.org
SA-RAG explores graph activation for evidence retrieval
Published on December 20, 2025, the paper presents SA-RAG, which propagates activation across weighted knowledge-graph connections to retrieve documents linked to relevant entities.
- 17 days ago arxiv.org
SAR as a reward signal for LLMs
A publication dated January 16, 2026 presents Self-Aligned Reward, compatible with PPO and GRPO, to pursue better reasoning with fewer tokens.
- 17 days ago x.com
Self-play for training code agents with real bugs
A publication dated December 26, 2025 describes Self-play SWE-RL, a method that trains an agent to insert and fix bugs in real repositories without human-labeled issues or natural-language problem descriptions.
- 17 days ago x.com
SETA launches 400 RL environments for terminal agents
On January 9, 2026, SETA announced training environments, an RL pipeline, and model weights for experiments with terminal agents.
- 17 days ago arxiv.org
SFT or reinforcement fine-tuning for continual post-training?
An article published on January 11, 2026 compares SFT and reinforcement fine-tuning in continual post-training of foundation models. Its title claims reinforcement fine-tuning naturally mitigates forgetting.
- 17 days ago github.com
slime v0.2.2 expands Int4-QAT and R3 support
Published on January 18, 2026, the slime v0.2.2 version announcement highlights memory and performance improvements, Int4-QAT training, and R3 support with DeepEP and MTP.
Let's assess your project

I reply with scope and a proposal.