


AI and infrastructure news
Filter by type: All83
- 18 days ago arxiv.org
Socratic-Zero uses agents to generate reasoning curricula
Published on October 28, 2025, the paper presents a method for generating reasoning data without human labels and reports results across seven mathematical reasoning benchmarks.
- 18 days ago huggingface.co
Expert trajectories for training language models
On October 31, 2025, a publication presented a method that uses expert trajectories to teach small language models to reason about difficult problems.
- 18 days ago zhuanlan.zhihu.com
RL training: data and infrastructure risks
Published on November 5, 2025, the publication argues that noisy feedback and complex infrastructure can make RL training unstable.
- 18 days ago huggingface.co
SmolDataEnvs: open collection of 5,000 verifiable RL tasks for small models
The open source SmolDataEnvs collection gathers 5,000 verifiable reinforcement learning environment tasks aimed at programming and data science, with evaluations and training components included.
- 18 days ago github.com
SkyRL tx v0.0.2 enables multi-LoRA training
On October 14, 2025, version 0.0.2 of the open SkyRL tx backend added support for training multi-LoRA models through the Tinker API.
- 19 days ago x.com
Training terminal agents in Dockerized RL environments
A post published on June 24, 2026 describes 14,600 Dockerized reinforcement-learning environments and an outcome-only DPPO recipe. A 9B model reached 27% on Terminal-Bench 2.0.
- 19 days ago github.com
RL environments and training code for language models
On September 26, 2026, Xiaomi MiMo published reinforcement learning environments, training code, and a dataset for experiments with language models.
- 19 days ago github.com
SQL-based replay buffer sampling
A post published on August 16, 2026 describes weighted top-k sampling in SQL and reports selecting 8,192 rows from 50 million in about 1.1 seconds on a laptop.
- 19 days ago x.com
AutoDecompiler applies RL to iterative decompilation
A post dated June 25, 2026 describes a model using reinforcement learning and direct feedback across multiple stages of decompilation.
- 19 days ago x.com
CodeMidas creates RL training tasks from code
In a post dated September 21, 2026, Xiaomi describes CodeMidas, which uses agents to generate 5,545 executable tasks in 23 languages from open-source codebases.
- 19 days ago
 arxiv.org
CodeMidas proposes generating RL tasks from code
On September 21, 2026, CodeMidas presented a pipeline that converts features from open-source projects into executable reinforcement-learning environments for programming.
- 19 days ago arxiv.org
How to evaluate asynchronous RL for agent post-training
A post published on July 9, 2026 discusses asynchronous RL for language-model post-training, updates as rollouts arrive, and stability techniques.
- 19 days ago arxivb.org
Directing RL compute toward harder problems
An article published on September 18, 2026, reports that the adaptive Never Give Up method samples until success to direct reinforcement-learning training compute toward harder problems in LLMs.
- 19 days ago huggingface.co
Explore reinforcement environments and run rollouts
An interactive Space published on September 29, 2026 lets engineers inspect reinforcement-learning environments and run rollouts. Its approach can inform internal evaluation and testing tools.
- 19 days ago x.com
How to measure RL gains on software engineering tasks
A post dated September 21, 2026 reports that MiMo Pro's DeepSWE score rose from 58.41 to 72.57 after reinforcement learning runs.
- 19 days ago x.com
How RL Could Expand Skills Learned Through SFT
A post published on July 11, 2026, presents the hypothesis that RL can separate useful SFT components into reusable skills and routing rules.
- 19 days ago arxiv.org
Two-phase distillation for multitask models
A paper published on June 30, 2026 studies consolidating reinforcement-learning specialists into a multitask model through off-policy and on-policy distillation.
- 19 days ago x.com
On-policy distillation for consolidating specialist models
MOPD trains a student model on its own completions and uses token-level probabilities from multiple teachers to transfer specialist capabilities.
- 19 days ago arxiv.org
DreamSmooth smooths sparse rewards in RL
Presented in an ICLR paper published on June 28, 2026, DreamSmooth applies temporal reward smoothing in model-based RL and was evaluated on RoboDesk and Shadow Hand.
- 19 days ago arxiv.org
EfficientRollout speeds up RL rollouts for LLMs
A paper dated July 5, 2026 describes system-adaptive self-speculative decoding and reports up to 19.6% faster rollout generation.
- 19 days ago github.com
FrontierSmith publishes 200 open-ended RL problems
On September 28, 2026, FrontierSmith published a repository of 200 problems for studying reinforcement learning on challenging, open-ended tasks.
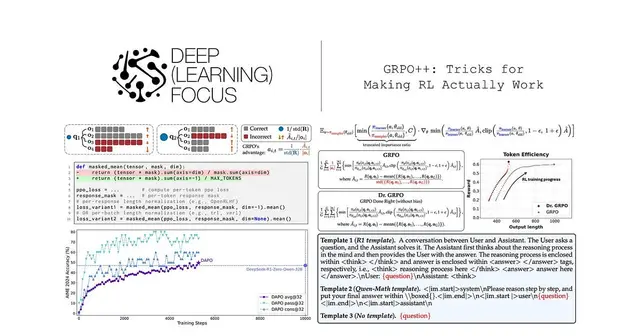
GRPO and OPD: practical paths for post-training
A publication dated August 26, 2026 presents two resources on post-training with reinforcement learning: one on scaling vanilla GRPO and another focused on OPD.
- 19 days ago
 unsloth.ai
GRPO for reasoning model training: Unsloth’s guide
Published on September 26, 2026, Unsloth’s guide covers reinforcement learning from beginner to advanced and presents the use of GRPO to train reasoning models.
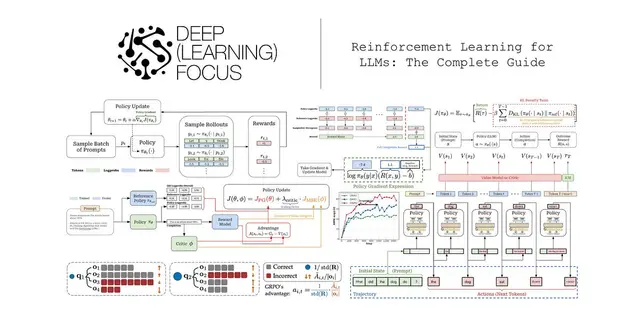
A reinforcement learning guide for language models
Published on August 24, 2026, the guide connects reinforcement learning fundamentals to language-model training methods, including policy gradients, REINFORCE, and different ways to define states and rewards.
- 19 days ago arxiv.org
Privileged information may affect long reasoning in models
An article dated July 7, 2026 reports degradation in long reasoning trajectories after self-distillation with privileged information, across five models evaluated on AIME.
- 19 days ago arxiv.org
LED explores intermediate layers in reasoning models
An article published on July 10, 2026, reports that Latent Exploration Decoding uses intermediate-layer distributions to expand exploration without additional training.
- 19 days ago arxiv.org
LENS combines image reasoning and segmentation with RL
The article presents LENS, a framework using reinforcement learning to jointly optimize reasoning and text-guided image segmentation.
- 19 days ago esraasaleh.com
Contraction operators in RL: from concept to internal learning
Published on September 12, 2026, the article presents a visual, concise approach to explaining contraction operators, a fundamental concept in reinforcement learning.
Optimizing evaluable objectives without RL
A post dated August 27, 2026, opens a series on alternatives to reinforcement learning and introduces sampling methods for optimizing evaluable objectives.
- 19 days ago arxiv.org
Paper evaluates LLM-as-a-Judge feedback in training
Published on September 19, 2026, the paper studies using the language model itself to provide feedback during training and compares this approach with frozen reward models trained on human preferences.
- 19 days ago x.com
Policy gradients: from derivation to practical evaluation
Published on August 30, 2026, the article reviews foundational reinforcement learning work, derives the policy gradient algorithm, and discusses its variants.
- 19 days ago arxiv.org
Positional encodings: comparing alternatives to RoPE
A study published on September 29, 2026 examines RoPE’s bias toward nearby tokens and alternatives evaluated across different configurations.
- 19 days ago drive.google.com
Post compares OPD and RL efficiency in model training
Dated June 19, 2026, the post claims OPD can use compute and samples more efficiently than RL in finding high-reward reasoning traces.
- 19 days ago x.com
ProRL Agent separates rollouts from LLM policy training
Published on September 30, 2026, ProRL Agent describes open-source rollout infrastructure that separates trajectory generation, environment orchestration, and evaluation from policy optimization for multi-turn agents.
- 19 days ago arxiv.org
Verified reasoning without updating model weights
A post published on June 23, 2026 proposes keeping a language model frozen and retrieving verified reasoning from an external pool, with logical verification as a key challenge.
- 19 days ago fa.bianp.net
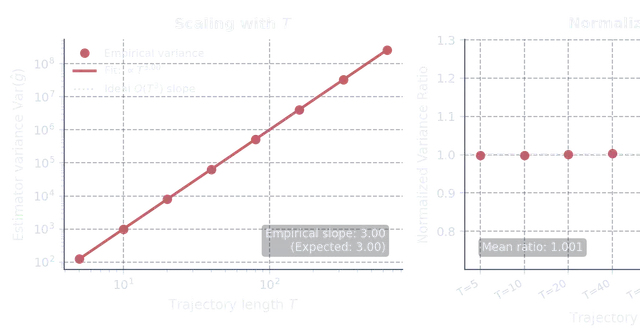
REINFORCE: policy gradients and variance
A post published on July 12, 2026 derives the REINFORCE estimator without differentiating through the environment and analyzes how variance depends on trajectory length.
- 19 days ago x.com
RubricEM uses step-by-step criteria to train research agents
Published on July 5, 2026, the work describes agents that create evaluation criteria before researching and reuse lessons from assessed attempts.
- 19 days ago github.com
RULER turns agent evaluations into rewards for GRPO
A September 17, 2026 post from OpenPipe ART describes how LLM-ranked agent trajectories can produce rewards for agent training.
- 19 days ago x.com
Sandbox infrastructure: a scale reference
A publication dated September 22, 2026 reports that a production-scale compute unit spans about 160 nodes and supports more than 380,000 concurrent sandboxes.
- 19 days ago arxiv.org
On-Policy Self-Distillation for Reasoning in LLMs
A paper dated September 28, 2026 describes a training method that combines trajectories generated by the student with dense teacher supervision at each token.
Let's assess your project

I reply with scope and a proposal.