


AI and infrastructure news
Filter by type: Article16
- 17 days ago blog.ml.cmu.edu
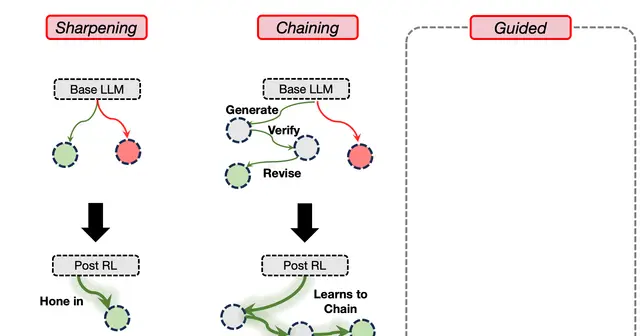
Exploration in RL for training LLMs on hard tasks
A CMU blog post published on January 31, 2026 describes three exploration regimes and the risks of stagnation and interference in reinforcement learning.
- 17 days ago
 unsloth.ai
GRPO with 380K context on a 192 GB GPU
On January 15, 2026, Unsloth documentation described long-context GRPO fine-tuning and stated that its batching algorithms enable 380K context for gpt-oss on a 192 GB GPU.
- 17 days ago alphaxiv.org
LoRA for RLVR: averaging specialists beats gating in reported tests
A paper dated January 3, 2026, examines practical PEFT strategies for multi-domain RLVR and reports interference during joint training. In the experiments described, averaging specialist LoRA weights and continuing training outperformed the tested gating method.
- 17 days ago aweers.de
RL methods for reasoning models
An article published on March 16, 2026, surveys reinforcement learning methods used with language models and offers engineering teams a starting point for comparison.
RL training systems: rollout challenges and pass@k results
An article published on December 21, 2025, covers rollout challenges in RL training and varied findings on pass@k performance.
- 17 days ago
 hgpu.org
Online RL for HPC code generation with real-machine benchmarks
Published on February 15, 2026, the paper describes online reinforcement learning, rewarded by benchmarks on real machines, to improve HPC code generation. Runtime performance of generated code is not guaranteed.
- 17 days ago rocm.blogs.amd.com
RLHF on AMD GPUs: deployment with ROCm 7.0
An AMD article published on March 2, 2026 describes using verl for RLHF training on AMD GPUs, with ROCm optimizations and Docker scripts, and presents throughput and convergence results.
- 17 days ago zhuanlan.zhihu.com
RL training: data and infrastructure risks
Published on November 5, 2025, the publication argues that noisy feedback and complex infrastructure can make RL training unstable.
- 18 days ago arxivb.org
Directing RL compute toward harder problems
An article published on September 18, 2026, reports that the adaptive Never Give Up method samples until success to direct reinforcement-learning training compute toward harder problems in LLMs.
GRPO and OPD: practical paths for post-training
A publication dated August 26, 2026 presents two resources on post-training with reinforcement learning: one on scaling vanilla GRPO and another focused on OPD.
- 18 days ago unsloth.ai
GRPO for reasoning model training: Unsloth’s guide
Published on September 26, 2026, Unsloth’s guide covers reinforcement learning from beginner to advanced and presents the use of GRPO to train reasoning models.
A reinforcement learning guide for language models
Published on August 24, 2026, the guide connects reinforcement learning fundamentals to language-model training methods, including policy gradients, REINFORCE, and different ways to define states and rewards.
- 18 days ago esraasaleh.com
Contraction operators in RL: from concept to internal learning
Published on September 12, 2026, the article presents a visual, concise approach to explaining contraction operators, a fundamental concept in reinforcement learning.
Optimizing evaluable objectives without RL
A post dated August 27, 2026, opens a series on alternatives to reinforcement learning and introduces sampling methods for optimizing evaluable objectives.
- 18 days ago drive.google.com
Post compares OPD and RL efficiency in model training
Dated June 19, 2026, the post claims OPD can use compute and samples more efficiently than RL in finding high-reward reasoning traces.
- 18 days ago fa.bianp.net
REINFORCE: policy gradients and variance
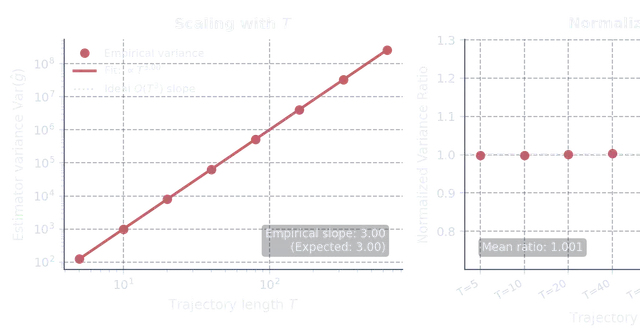
A post published on July 12, 2026 derives the REINFORCE estimator without differentiating through the environment and analyzes how variance depends on trajectory length.
Let's assess your project

I reply with scope and a proposal.