


AI and infrastructure news
Filter by type: Paper30
- 13 days ago
 arxiv.org
QwenGyre: elastic RL for training long-horizon agents
Alibaba Qwen presented QwenGyre, an elastic RL framework that reallocates GPUs between rollout and training and groups branched agent runs into trajectory trees with shared prefixes, with a reported speedup of up to 1.85x over Colocate.
- 18 days ago arxiv.org
Adapting models to Q, a language used in finance
A technical report dated January 9, 2026 presents an open-source approach to adapting language models to Q, a programming language used in quantitative finance.
- 18 days ago arxiv.org
Search agents can check evidence against noise
Published on October 28, 2025, the paper describes an agent that sets search goals and checks whether retrieved evidence meets them, aiming to resist misleading cues.
- 18 days ago arxiv.org
Self-distillation may support continual learning without rewards
A post published on February 16, 2026 describes a self-distillation technique for training models on new tasks without a reward function, with the aim of reducing catastrophic forgetting.
- 18 days ago arxiv.org
BAPO aims to stabilize off-policy training for LLMs
Published on October 23, 2025, the paper presents BAPO, a method using balanced policy optimization and adaptive clipping for partial rollout and experience reuse scenarios.
- 18 days ago arxiv.org
CogRouter adjusts agent reasoning at each step
Published on February 16, 2026, the material describes four cognitive levels for LLM agents and reports 82.3% benchmark success for a 7B model.
- 18 days ago arxiv.org
Stabilizing reinforcement learning with LLMs
A Qwen team article published on December 16, 2025, examines instability in reinforcement learning for language models and highlights differences between training and inference, old and new policies, importance sampling, and routing replay.
- 18 days ago arxiv.org
EditScore applies reward models to image editing
A post dated October 25, 2025 presents a family of reward models for evaluating and guiding complex image edits, with reported results on EditReward-Bench.
- 18 days ago arxiv.org
JustRL tests simple RL on 1.5B reasoning models
Published on January 4, 2026, the paper describes single-stage training with fixed hyperparameters and reports average accuracies of 54.9% and 64.3% across two 1.5B reasoning models.
- 18 days ago nature.com
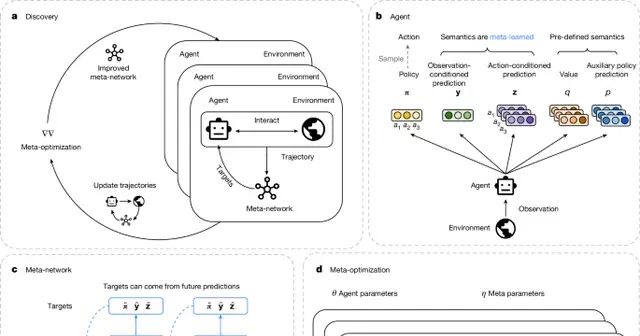
Meta-learning proposes update rules for reinforcement learning
Published on October 24, 2025, the article presents DiscoRL, a method that learns reinforcement learning update rules across agents and environments and reports leading results on benchmarks including Atari and ProcGen.
- 18 days ago arxiv.org
KL regularization in RL may defy intuitions about diversity
Published on October 24, 2025, the article examines reverse KL and forward KL regularization in reinforcement learning and finds that the usual distinction between mode-seeking and mass-covering does not necessarily apply.
- 18 days ago arxiv.org
Multimodal RL: stability with a single rollout
A December 23, 2025 publication reports that advantage shaping with an entropy bonus stabilized a single-rollout approach to multimodal reinforcement learning.
- 18 days ago arxiv.org
SA-RAG explores graph activation for evidence retrieval
Published on December 20, 2025, the paper presents SA-RAG, which propagates activation across weighted knowledge-graph connections to retrieve documents linked to relevant entities.
- 18 days ago arxiv.org
SAR as a reward signal for LLMs
A publication dated January 16, 2026 presents Self-Aligned Reward, compatible with PPO and GRPO, to pursue better reasoning with fewer tokens.
- 18 days ago arxiv.org
SFT or reinforcement fine-tuning for continual post-training?
An article published on January 11, 2026 compares SFT and reinforcement fine-tuning in continual post-training of foundation models. Its title claims reinforcement fine-tuning naturally mitigates forgetting.
- 18 days ago arxiv.org
Socratic-Zero uses agents to generate reasoning curricula
Published on October 28, 2025, the paper presents a method for generating reasoning data without human labels and reports results across seven mathematical reasoning benchmarks.
- 18 days ago huggingface.co
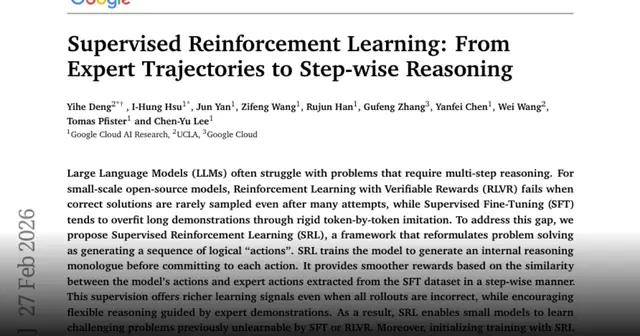
Expert trajectories for training language models
On October 31, 2025, a publication presented a method that uses expert trajectories to teach small language models to reason about difficult problems.
- 19 days ago arxiv.org
CodeMidas proposes generating RL tasks from code
On September 21, 2026, CodeMidas presented a pipeline that converts features from open-source projects into executable reinforcement-learning environments for programming.
- 19 days ago arxiv.org
How to evaluate asynchronous RL for agent post-training
A post published on July 9, 2026 discusses asynchronous RL for language-model post-training, updates as rollouts arrive, and stability techniques.
- 19 days ago arxiv.org
Two-phase distillation for multitask models
A paper published on June 30, 2026 studies consolidating reinforcement-learning specialists into a multitask model through off-policy and on-policy distillation.
- 19 days ago arxiv.org
DreamSmooth smooths sparse rewards in RL
Presented in an ICLR paper published on June 28, 2026, DreamSmooth applies temporal reward smoothing in model-based RL and was evaluated on RoboDesk and Shadow Hand.
- 19 days ago arxiv.org
EfficientRollout speeds up RL rollouts for LLMs
A paper dated July 5, 2026 describes system-adaptive self-speculative decoding and reports up to 19.6% faster rollout generation.
- 19 days ago arxiv.org
Privileged information may affect long reasoning in models
An article dated July 7, 2026 reports degradation in long reasoning trajectories after self-distillation with privileged information, across five models evaluated on AIME.
- 19 days ago arxiv.org
LED explores intermediate layers in reasoning models
An article published on July 10, 2026, reports that Latent Exploration Decoding uses intermediate-layer distributions to expand exploration without additional training.
- 19 days ago arxiv.org
LENS combines image reasoning and segmentation with RL
The article presents LENS, a framework using reinforcement learning to jointly optimize reasoning and text-guided image segmentation.
- 19 days ago arxiv.org
Paper evaluates LLM-as-a-Judge feedback in training
Published on September 19, 2026, the paper studies using the language model itself to provide feedback during training and compares this approach with frozen reward models trained on human preferences.
- 19 days ago arxiv.org
Positional encodings: comparing alternatives to RoPE
A study published on September 29, 2026 examines RoPE’s bias toward nearby tokens and alternatives evaluated across different configurations.
- 19 days ago arxiv.org
Verified reasoning without updating model weights
A post published on June 23, 2026 proposes keeping a language model frozen and retrieving verified reasoning from an external pool, with logical verification as a key challenge.
- 19 days ago arxiv.org
On-Policy Self-Distillation for Reasoning in LLMs
A paper dated September 28, 2026 describes a training method that combines trajectories generated by the student with dense teacher supervision at each token.
- 19 days ago github.com
WANDR: an environment for evaluating agentic search
In a post published on July 14, 2026, Perplexity says it is making available a reinforcement-learning and evaluation environment for agentic search, synthesized from production traces with weak human supervision.
Let's assess your project

I reply with scope and a proposal.