


AI and infrastructure news
Filter by type: All90
Ming 3 TTS ranks first among open voice models in Artificial Analysis leaderboard
The post reports that the open Ming 3 TTS model, published by inclusionAI, leads the Artificial Analysis ranking among open TTS models and slightly ahead of Fish Audio Drama 3. Teams that self-host speech synthesis should evaluate candidates on their own data before switching models.
- 1 day ago x.com
Dessa: full-duplex speech-to-speech model announced for consumer GPUs
A post announces Dessa, a full-duplex speech-to-speech model that, according to its author, was trained only on speech and runs on consumer GPUs. Relevant to locally hosted conversational voice.
- 1 day ago x.com
Open TTS Leaderboard adds 31M and 35B models and the UTMOS metric
The Open TTS Leaderboard update compares a 31M-parameter open model with a 35B one on English WER and adds the UTMOS metric for speech naturalness.
- 3 days ago github.com
Phonon 31M: open TTS running on Apple's Neural Engine via Swift
Post on a Swift port of the open Phonon 31M TTS model, using CoreML on the Neural Engine, with 103 voices and latency and speed figures stated by the author.
- 4 days ago x.com
Ant Ling releases five Ming-3.0 speech models with open weights
Ant Ling announced the open-source release of five Ming-3.0 models covering speech synthesis variants, audio understanding, dialogue and automatic speech recognition for dialects.
- 4 days ago x.com
Streaming ASR: decoding speech without seeing future audio
The Tongyi Speech AI post explains streaming speech recognition, where words must be committed while the speaker is still talking. Latency and lookahead shape the model and decoder design for live voice applications.
- 4 days ago x.com
Kyutai releases smaller Pocket TTS versions with up to 1.9M parameters
Kyutai Labs has announced smaller Pocket TTS versions at 18.2M, 6.9M and 1.9M parameters, and claims the 1.9M model runs 103x faster than real time on a single CPU core, with voice cloning.
- 4 days ago x.com
Open source TTS models smaller than Kokoro, with voice cloning
The post announces open source text-to-speech models about half the size of Kokoro (82M parameters), with claimed gains in naturalness and accuracy and support for voice cloning. They could lower the cost of running speech synthesis locally.
- 4 days ago x.com
Phonon: 40M-parameter multilingual TTS model for locally run voice
According to the author's announcement, Phonon is a text-to-speech model of about 40M parameters, with multiple languages, a voice library, and local use through the speech-to-speech package.
- 4 days ago x.com
Phonon: open 31M-parameter TTS running in the browser via WebGPU
Post reports a port of Phonon, an open 31M-parameter text-to-speech model from GradiumAI, running fully in the browser via WebGPU in half precision, with the author citing about 47x real time on an M4 Pro and 7x on a Phone 13 Pro.
- 4 days ago github.com
On-device voice on iPhone without the cloud: open-source app combines Phonon TTS and Pipecat
An open-source iOS app runs speech-to-text and text-to-speech entirely on the phone, using embedded Pipecat, Apple's SpeechAnalyzer and the Gradium Phonon 31M model, with no network inference.
- 5 days ago github.com
Pull request adds streaming Drama-3 TTS to the speech-to-speech pipeline
A pull request proposes Drama-3, from Fish Audio, as a streaming text-to-speech backend in a speech-to-speech repository, with optional voice cloning and expressive intonations such as whispers and laughter.
- 6 days ago x.com
AuroraASR-1M: offline speech recognition on CPU with a 1 MB model
The post describes a 949K-parameter Conformer-CTC model for English, 1.06 MB in INT8, Apache 2.0 licensed, running at about 436x real time on one CPU thread with an 11.43% WER on test-clean.
- 6 days ago github.com
Local voice-cloning dubbing: OpenVoice on common hardware
The post describes an AI agent using OpenVoice, an open-source instant voice-cloning model from MIT and MyShell, to dub a Polish film while keeping the dialogue synchronized, on a Mac mini M4 with 16 GB.
- 15 days ago x.com
Artificial Analysis: HeyGen Voice tops controlled voice TTS ranking
Artificial Analysis ranked HeyGen Voice first in the Controlled Voice TTS Arena, with an Elo of 1,201 across 8 cloned voices in US and UK English, ahead of competing commercial voice models.
- 15 days ago huggingface.co
Qwen3-TTS 1.7B: open-source voice cloning with emotion and accent controls
The post presents an open-source 1.7B text-to-speech model for voice cloning, with controls for emotion, age, tone and accent, plus multilingual support. For companies, a self-hosted evaluation means checking license, languages and controls before any use.
- 15 days ago huggingface.co
Whistle: 16.9 MB speech-to-text model built for on-device use
Cactus-Compute published Whistle, a 16.9 MB speech-to-text model for on-device use. The author claims it rivals Whisper base. For companies handling sensitive audio, the announcement opens a case for local transcription.
- 16 days ago x.com
Voice clones of non-native English speakers rated more human: what it means for companies
A NeurIPS 2026 paper cloned the voices of 86 non-native English speakers using three voice-synthesis systems. In 4,000 human ratings, the clones were judged warmer, more authoritative and more human, which raises trust risks for voice channels.
- 17 days ago models.handy.computer
Multilingual speech-to-text benchmark for local models in transcribe.cpp on a notebook
Site comparing accuracy and speed of speech-to-text models supported by transcribe.cpp, measured per language on FLEURS, with performance data from a notebook CPU/GPU (4750U).
- 17 days ago x.com
Single-voice 9MB TTS model distilled from Kokoro-82M for local voice output
A post describes a single-voice, single-language text-to-speech model of about 9MB of weights, distilled from Kokoro-82M and aimed at local voice output on resource-constrained devices.
- 17 days ago inworld.ai
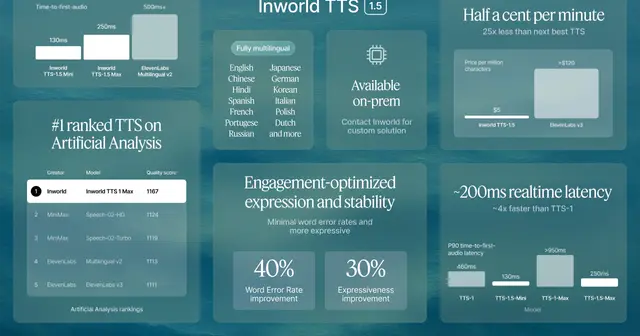
Human evaluation highlights speech synthesis across four categories
On November 6, 2025, Artificial Analysis reported that a speech synthesis model led its Speech Arena, a blind human preference evaluation across four real-world speech categories.
- 17 days ago x.com
Private evaluation data to reduce ASR test leakage
On May 6, 2026, the Open ASR Leaderboard added private evaluation data from Appen and DataoceanAI to reduce test-set contamination and overfitting.
- 17 days ago huggingface.co
Evaluating real-time spoken dialogue for business
A January 16, 2026 publication describes an interactive spoken-dialogue model with an Apache 2.0 license and a dual-brain architecture aimed at low latency. Learn how to assess a voice application before integrating it.
- 17 days ago x.com
How to evaluate voice models for products and operations
On November 6, 2025, Artificial Analysis reported that Inworld TTS 1 Max led Speech Arena, a blind comparison of text-to-speech models based on human evaluations.
- 17 days ago docs.vllm.ai
Evaluating speech recognition serving with vLLM
A publication dated January 29, 2026, says vLLM has supported Qwen3-ASR since launch and points to a guide for running the model.
- 17 days ago ai.google.dev
Planning live translation for multilingual experiences
API documentation published on June 9, 2026, covers live translation. Learn how to assess an implementation for your company’s workflows.
- 17 days ago github.com
Prompt-based audio editing: what companies can evaluate
A StepFun post published on November 8, 2025 describes a 3-billion-parameter model for audio editing and multilingual speech generation.
- 17 days ago github.com
FireRedVAD: voice detection in over 100 languages
The FireRedVAD repository describes voice activity and audio event detection, with stated support for over 100 languages. Learn how to assess its integration into speech pipelines.
- 17 days ago github.com
C inference enables integrated speech transcription
The antirez/qwen-asr repository provides C inference for 0.6B and 1.7B speech-recognition models, with potential use in transcription bots and voice-controlled interfaces.
LEMAS publishes a 150,000-hour speech dataset
A January 12, 2026 publication presents an audio dataset with 150,000 hours across 10 languages, word-level timestamps, and the generative models LEMAS-TTS and LEMAS-Edit.
- 17 days ago github.com
Local Studio proposes support for ROCm, speech, images and video
A pull request in the Local Studio repository, published on February 9, 2026, describes proposed support for ROCm, speech input and output, images, and video.
- 17 days ago x.com
Microsoft describes long-audio transcription with speaker diarization
An article published on March 2, 2026 describes a model that Microsoft says transcribes up to 60 minutes of audio in one pass and supports more than 50 languages.
- 17 days ago x.com
Pocket TTS: speech synthesis on laptops without a GPU
In a post published on January 13, 2026, Kyutai Labs introduced Pocket TTS, a 100-million-parameter speech synthesis model with voice cloning that runs on a laptop without a GPU.
- 17 days ago x.com
Evaluating speech recognition for distant audio
On June 10, 2026, Cohere said its open speech-recognition model ranked first on the Far-Field ASR benchmark. The result may inform evaluations of systems for distant audio.
- 17 days ago github.com
Speech recognition across more than 1,600 languages
On November 10, 2025, Meta announced open-source speech recognition models and a dataset covering more than 1,600 languages, including 500 described as previously unsupported.
- 17 days ago github.com
Open-source repository provides a starting point for voice agents
Published on February 6, 2026, the repository offers a basis for engineers to create voice agents with open-source models.
- 17 days ago gradium.ai
TTS for More Accurate Pronunciation of Structured Data
In a June 10, 2026 post, Gradium says an update to its TTS model improves pronunciation of spelled-out words, acronyms, email addresses, phone numbers, and codes.
- 17 days ago github.com
UNITTS combines inference and benchmarking for speech synthesis
A post dated June 9, 2026 presents UNITTS, a toolkit for inference and benchmarking of open-source TTS models, with support for Chatterbox and Fish Audio s2-pro.
- 17 days ago vllm.ai
vLLM reports streaming inputs and a real-time WebSocket API
On February 11, 2026, the vLLM blog described streaming inputs and a WebSocket API for audio, video, robotics, and low-latency applications.
- 17 days ago x.com
VoxCPM: expressive speech without a tokenizer
Published on January 31, 2026, the post describes a speech synthesis system using continuous representations, zero-shot voice cloning, and expressive generation.
Let's assess your project

I reply with scope and a proposal.