


AI and infrastructure news
Filter by type: All90
- 18 days ago sesame.com
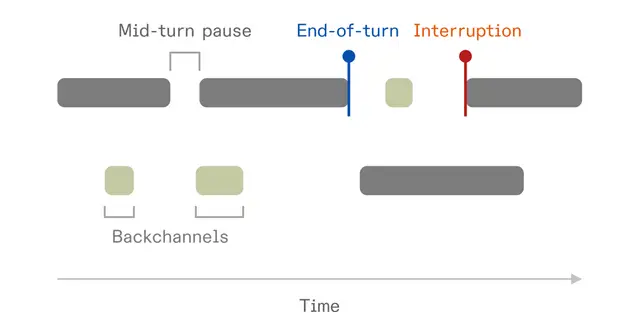
TurnBench evaluates turn-taking in spoken dialogue
Open benchmark with 30 hours of dyadic speech annotated by three people, a scoring protocol based on conversation analysis, and results from 14 systems for measuring turn-taking.
- 18 days ago github.com
Structuring transcription for long recordings
A description published on September 17, 2025 presents a Python tool that splits audio using voice activity detection, processes parallel calls, and accepts multiple media formats.
- 18 days ago x.com
Voice app adds support for custom models in five languages
A post dated November 11, 2024, says the e2-f5-tts Gradio app now supports custom F5-TTS finetunes for Spanish, Hungarian, German, Portuguese, and Greek.
- 18 days ago x.com
Moonshine ASR joins the Transformers library
A post published on January 20, 2025 announces Moonshine’s integration into Transformers: the model uses Rotary Position Embeddings and accepts audio of any duration.
- 18 days ago x.com
Audio reasoning benchmark reports 92%
An Artificial Analysis report records a 92% score on Big Bench Audio for an audio model and compares time to first token with and without reasoning.
- 18 days ago huggingface.co
Assess French speech synthesis for your business
A post by PHBJT, published on September 25, 2024, points to a French text-to-speech model and mentions other speech-generation options.
- 18 days ago github.com
Audio codec for Speech LLMs: parallel tokens and streaming
In a post published on October 17, 2025, Meituan presented an open-source audio codec optimized for Speech LLMs, with parallel semantic and acoustic tokens at 16.7 Hz and low-latency streaming decoding.
- 18 days ago x.com
Evaluating real-time speech inference
Published on September 18, 2024, the article presents Moshi, a 7.6-billion-parameter speech-to-speech model, and Mimi, a streaming audio codec.
- 18 days ago artificialanalysis.ai
Comparing speech-to-text options by quality, speed and cost
On June 24, 2024, Artificial Analysis published a comparison of speech-to-text models by word error rate, speed and price, with a ranking intended to guide selection by use case.
- 18 days ago x.com
E2-F5-TTS adds an interface for voice-model tuning
On October 21, 2024, the E2-F5-TTS repository presented a Gradio app for tuning the model with user-supplied audio and automatically transcribing clips.
- 18 days ago huggingface.co
Multilingual speech: evaluating FireRedTTS 2
Published on September 17, 2025, the article presents an open speech synthesis model supporting long-form conversation, multilingual voice cloning, and low-latency generation.
- 18 days ago x.com
FireRedChat: full-duplex voice for assistants
A post dated October 7, 2025 describes a modular voice interaction system with cascade and semi-cascade modes, interruption handling, end-of-speech detection, and real-time responses.
- 18 days ago github.com
Hibiki: streaming speech translation
A repository published on February 6, 2025 presents a decoder-only model for simultaneous French-to-English and English-to-French speech translation, trained on synthetic data.
- 18 days ago
 arxiv.org
MaskGCT: zero-shot speech synthesis and voice cloning
Published on October 24, 2024, the MaskGCT paper presents a text-to-speech model that the publication says can clone a voice from five seconds of speech.
- 18 days ago x.com
Mini-Omni-Reasoner combines reasoning and speech
A September 22, 2025 post describes an architecture that alternates silent reasoning with spoken tokens, alongside a new dataset and reported gains in arithmetic reasoning and contextual understanding.
- 18 days ago x.com
Parler-TTS: evaluating controllable voice models
Published on August 8, 2024, the announcement presents Mini and Large v1, models trained on 45,000 hours of speech, with voice controls set through text prompts.
- 18 days ago x.com
Piper offers local multilingual neural speech synthesis
Published on January 7, 2025, the text describes Piper, a local system that converts text to speech with multiple voices, languages, and customizable options.
- 18 days ago github.com
Qwen3-Omni: multimodal models with speech
On September 22, 2025, Qwen introduced three models combining text, images, audio, and video, with speech input and output.
- 18 days ago modal.com
Streaming audio transcription: Modal's example
On August 6, 2025, Modal presented an example deployment of a streaming speech recognition service using Kyutai STT.
- 18 days ago x.com
Streaming TTS points to multi-voice dialogue
A September 15, 2025 post describes a long-form streaming speech system that interleaves text and audio for contextual dialogue with multiple speakers.
- 18 days ago x.com
Local TTS with voice cloning: risks and implementation
On February 15, 2025, Zonos announced an expressive speech synthesis beta with voice cloning, open models, and a cross-platform local launcher.
- 18 days ago github.com
Ultravox and real-time voice applications
The GitHub repository presents Ultravox as a fast multimodal LLM for real-time voice. Published on November 18, 2024, the project makes its source code available for examination.
- 18 days ago x.com
VoiceCraft: speech editing and zero-shot synthesis
Published on August 25, 2024, the text describes VoiceCraft, a model that edits speech and generates voices from a few seconds of reference audio.
- 18 days ago x.com
XEUS: multilingual speech encoder with code and checkpoints
On July 1, 2024, WavLab announced XEUS, a speech encoder trained on more than 1 million hours of audio and covering over 4,000 languages. Code, checkpoints, and data were made available.
- 19 days ago github.com
Breeze TTS 2 opens model weights
On August 26, 2026, BreezeBlue announced open weights for Breeze TTS 2 and said the model leads a voice evaluation arena.
- 19 days ago x.com
Breeze TTS 2: Multilingual voice generation in streaming
A publication dated August 25, 2026 describes a speech synthesis model supporting 50 languages, text-prompt voice generation, and streaming output.
- 19 days ago github.com
CocktailASR-1 transcribes a selected voice in overlapping audio
Published by Xiaomi on September 16, 2026, CocktailASR-1 uses reference voiceprints to transcribe a chosen speaker in mixed audio. The publication reports support for English and Chinese.
- 19 days ago arxiv.org
Extending frozen LLMs to understand audio
A paper dated September 28, 2026, proposes injecting audio-conditioned vectors into a frozen LLM's KV cache to add audio understanding without tuning model weights.
- 19 days ago x.com
Speaker diarization: evaluating label correction
A Google article published on October 4, 2026 describes a 4-billion-parameter model fine-tuned to correct speaker labels and reduce word-level diarization errors across four benchmarks.
- 19 days ago discourse.ubuntu.com
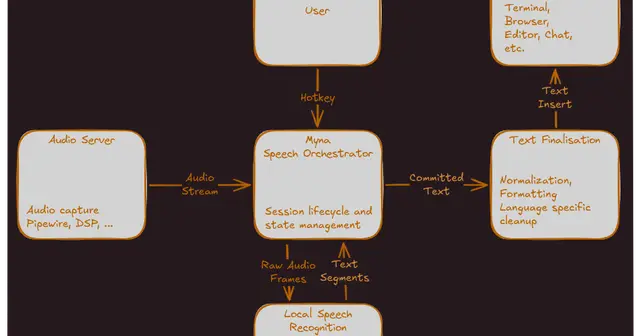
Local dictation on Ubuntu: assessing Project Myna
In a June 18, 2026 publication, Ubuntu describes Project Myna, a feature planned for Ubuntu 26.10 that aims to insert speech-to-text into the active application, with processing performed locally.
- 19 days ago github.com
FireRedAudio combines five speech tasks in one model
Published on August 27, 2026, FireRedAudio combines speech recognition and understanding, speech generation, and speech editing, using distinct representations for audio comprehension and generation.
- 19 days ago x.com
Index compares speech models across three capabilities
Published on June 23, 2026, the Artificial Analysis index combines three evaluation datasets to compare native Speech-to-Speech models.
- 19 days ago x.com
Local audio cleanup on Raspberry Pi 5: how to assess the use case
A post dated June 22, 2026 presents a 49,000-parameter model for acoustic echo cancellation, noise suppression, and dereverberation, with claimed performance of 21× real time on one Raspberry Pi 5 core.
- 19 days ago x.com
NVIDIA presents diarization for overlapping speech
Announcement dated September 23, 2026: Nemotron 3 Diarization identifies who spoke and when, including in overlapping speech, and supports up to eight speakers.
- 19 days ago github.com
OmniVoice: speech synthesis and voice cloning in 600+ languages
A publication dated September 6, 2026 describes a Python speech-synthesis project with zero-shot voice cloning, support for more than 600 languages, and configurable voice controls.
- 19 days ago x.com
Packed FlashAttention speeds up a Transformer vocoder
A July 20, 2026 publication reports a 48.64% increase in QPS for a Transformer vocoder after waveform reconstruction optimizations.
- 19 days ago arxiv.org
Phoenix-VAD: detecting the end of speech in voice dialogues
An article published on September 4, 2026 presents an LLM-based model for semantic end-of-speech detection in full-duplex streaming voice interactions, using sliding-window training.
- 19 days ago x.com
Phonon-1: evaluating local audio transcription
A post dated August 28, 2026 presents Phonon-1, a speech recognition model with 782 million parameters, a 415 MB download, and an Apache 2.0 license.
- 19 days ago moondream.ai
Photon 2.1 expands streaming ASR for self-hosted deployments
Moondream says Photon 2.1 adds streaming speech recognition for three models and beats each model’s reference engine in all comparable tests.
- 19 days ago github.com
ComfyUI plugin supports local voice and LoRA tuning
Published on August 25, 2026, the ComfyUI_VoxCPM_SM repository presents VoxCPM2 inference and LoRA fine-tuning with custom voice data, supporting low VRAM and quantized models.
Let's assess your project

I reply with scope and a proposal.