


AI and infrastructure news
Filter by type: Article11
- 18 days ago models.handy.computer
Multilingual speech-to-text benchmark for local models in transcribe.cpp on a notebook
Site comparing accuracy and speed of speech-to-text models supported by transcribe.cpp, measured per language on FLEURS, with performance data from a notebook CPU/GPU (4750U).
- 18 days ago inworld.ai
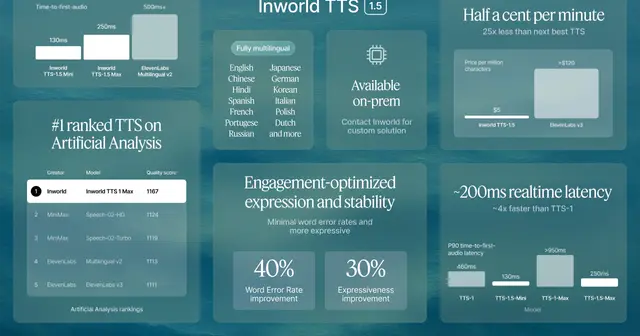
Human evaluation highlights speech synthesis across four categories
On November 6, 2025, Artificial Analysis reported that a speech synthesis model led its Speech Arena, a blind human preference evaluation across four real-world speech categories.
- 18 days ago ai.google.dev
Planning live translation for multilingual experiences
API documentation published on June 9, 2026, covers live translation. Learn how to assess an implementation for your company’s workflows.
LEMAS publishes a 150,000-hour speech dataset
A January 12, 2026 publication presents an audio dataset with 150,000 hours across 10 languages, word-level timestamps, and the generative models LEMAS-TTS and LEMAS-Edit.
- 18 days ago gradium.ai
TTS for More Accurate Pronunciation of Structured Data
In a June 10, 2026 post, Gradium says an update to its TTS model improves pronunciation of spelled-out words, acronyms, email addresses, phone numbers, and codes.
- 18 days ago vllm.ai
vLLM reports streaming inputs and a real-time WebSocket API
On February 11, 2026, the vLLM blog described streaming inputs and a WebSocket API for audio, video, robotics, and low-latency applications.
- 18 days ago sesame.com
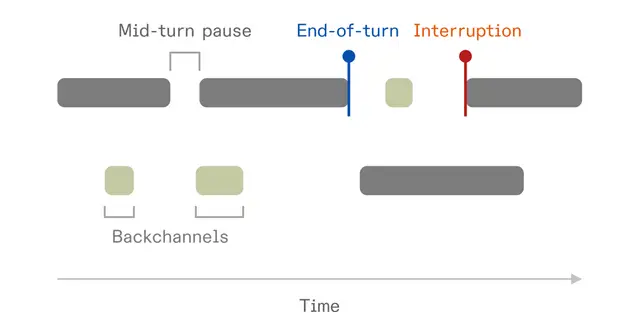
TurnBench evaluates turn-taking in spoken dialogue
Open benchmark with 30 hours of dyadic speech annotated by three people, a scoring protocol based on conversation analysis, and results from 14 systems for measuring turn-taking.
- 18 days ago artificialanalysis.ai
Comparing speech-to-text options by quality, speed and cost
On June 24, 2024, Artificial Analysis published a comparison of speech-to-text models by word error rate, speed and price, with a ranking intended to guide selection by use case.
- 18 days ago modal.com
Streaming audio transcription: Modal's example
On August 6, 2025, Modal presented an example deployment of a streaming speech recognition service using Kyutai STT.
- 19 days ago discourse.ubuntu.com
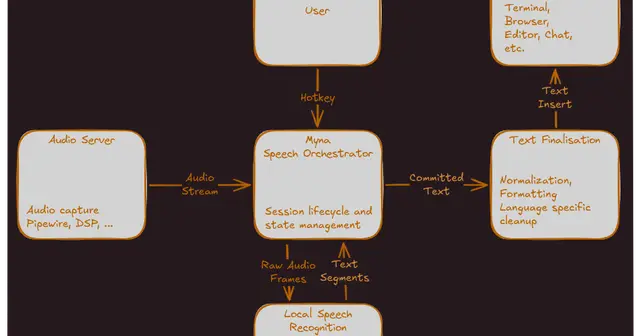
Local dictation on Ubuntu: assessing Project Myna
In a June 18, 2026 publication, Ubuntu describes Project Myna, a feature planned for Ubuntu 26.10 that aims to insert speech-to-text into the active application, with processing performed locally.
- 19 days ago moondream.ai
Photon 2.1 expands streaming ASR for self-hosted deployments
Moondream says Photon 2.1 adds streaming speech recognition for three models and beats each model’s reference engine in all comparable tests.
Let's assess your project

I reply with scope and a proposal.