


AI and infrastructure news
- C and C++Article
Linkers in C and C++: diagnosing build failures
A guide published on May 27, 2026, explains the linking process and how understanding it helps diagnose build and linker problems in C and C++.
- C and C++Article
Dynamic or static linking: weigh startup and disk use
Jordan Rose’s article, published on March 2, 2026, discusses the trade-off between startup time and disk space in dynamic and static linking strategies.
- C and C++Post
Linux Device Drivers and hardware communication
A post published on May 25, 2026 recommends Linux Device Drivers as an introduction to communication between the Linux kernel and hardware, for readers with some C and Unix system-call knowledge.
- C and C++Article
Linux documents bus lock detection on x86
Published on April 11, 2026, Linux kernel documentation covers detecting and handling bus locks on x86. Split locks can affect system performance.
- HardwareArticle
Lisuan begins shipping 6 nm 7G100 GPUs
On December 30, 2025, Lisuan reported that it had begun shipping its 6 nm 7G100 GPUs to its first customers.
- C and C++Article
Free book covers systems programming in C
Published on March 31, 2026, Dive into Systems covers systems programming, code optimization, and assembly across multiple architectures, using C as its foundation.
- LLM inferenceProject
llama.cpp adds Multi-Token Prediction support
On May 17, 2026, a pull request to the llama.cpp repository added support for MTP heads. The report cites 65 tokens per second for Qwen3.6-27B on an RTX 3090, versus 38 without MTP.
- LLM inferenceProject
llmfit helps assess models for local hardware
The llmfit repository, published on GitHub on February 21, 2026, analyzes local hardware to identify compatible models and estimate inference speed.
- LLM inferencePost
LMCache reuses KV cache across GPU, CPU and disk
On January 30, 2026, the description of the open-source LMCache project presented an LLM-serving extension that reuses KV states across GPUs, CPUs and local disks, including repeated text chunks beyond prefixes.
- Speech: TTS and ASRProject
Local Studio proposes support for ROCm, speech, images and video
A pull request in the Local Studio repository, published on February 9, 2026, describes proposed support for ROCm, speech input and output, images, and video.
- C and C++Docs
Linux Kernel locking: practices for reviewing concurrency
Published on June 9, 2026, Linux Kernel documentation offers a guide to kernel locking and concurrency practices. Companies can apply a structured review of synchronization in critical systems.
- C and C++Article
Locks in real-time Ubuntu: kernel concurrency and SMP
On June 10, 2026, Real-time Ubuntu documentation explained how kernel locks protect critical sections from context switches and preemption, including on multiprocessor systems.
- HardwareArticle
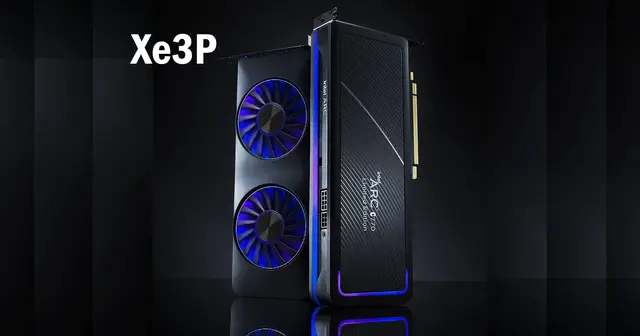
Log points to Intel Xe3P variants for discrete GPUs
A Wccftech article published on November 6, 2025, reports that a leaked log points to an Xe3P HPM variant for discrete GPUs and an LPM variant possibly linked to Nova Lake.
- LLM inferencePaper
LoPA uses lookahead to accelerate diffusion model inference
Published on January 11, 2026, the text presents LoPA, a training-free algorithm that uses lookahead to select token-filling orders in diffusion language models.
- Training and fine-tuningPost
LoRA as memory: evaluating data and rank
A post dated March 4, 2026 summarizes a study of how knowledge memory stored by LoRA scales and saturates with rank. QA and summaries produced more memory per token than raw passages.
- Training and fine-tuningPaper
LoRA as knowledge memory: limits to evaluate
Published on March 3, 2026, the paper analyzes LoRA adapters for updating language-model knowledge and examines capacity limits, modular scaling, and interference when merging modules.
- Reinforcement learningArticle
LoRA for RLVR: averaging specialists beats gating in reported tests
A paper dated January 3, 2026, examines practical PEFT strategies for multi-domain RLVR and reports interference during joint training. In the experiments described, averaging specialist LoRA weights and continuing training outperformed the tested gating method.
- LLM inferenceProject
Lucebox explores speculative inference on consumer GPUs
Published on May 9, 2026, the post presents Lucebox, a speculative inference server for heterogeneous hardware, and reports that Qwen3.6-27B reaches 120–200 tokens per second on an RTX 3090.
- Attention and model architecturePaper
Mamba-3 proposes fixed-state sequence modeling
Published on May 7, 2026, the post describes a non-Transformer language architecture that compresses context into a fixed-size state and claims decoding time constant with respect to sequence length.
- C and C++Article
Intel manuals detail 64-bit and IA-32 architectures
Published on December 25, 2025, Intel's official manuals describe the Intel 64 and IA-32 architectures and programming environment as a primary reference for low-level engineering.
- Reinforcement learningPost
MaxRL proposes another approach to RL with binary rewards
Published on February 9, 2026, the post describes MaxRL and reports up to 20 times greater test-time efficiency than GRPO.
- Attention and model architectureArticle
Attention mechanisms: comparing Transformer architectures
An article published on April 19, 2026, surveys more than 13 attention mechanisms and explains how they shape context and memory processing in Transformers and LLMs.
- C and C++Article
Measure memory and branch prediction to understand software performance
An article published on March 1, 2026 examines how the memory subsystem interacts with branch prediction and influences software performance.
- RAG and retrievalPaper
MegaRAG proposes multimodal graphs for RAG
Published on December 25, 2025, the paper describes a method that automatically builds knowledge graphs from visual documents to support retrieval and cross-modal reasoning.
- Training and fine-tuningPaper
Megatron-LM splits models across GPUs for training
A 2019 NVIDIA paper describes using model parallelism to train language models with billions of parameters by distributing weights across GPUs when they do not fit on one.
- Training and fine-tuningProject
GRPO improvements in a PyTorch notebook
A notebook published on February 15, 2026 analyzes improvements to a GRPO implementation, including constrained policy ratios, a KL term, and format rewards.
- C and C++Paper
Memory and performance: turning knowledge into diagnosis
Published on March 29, 2026, Ulrich Drepper’s article discusses memory for programmers and offers context for engineers investigating memory behavior and software performance.
- C and C++Article
Memory and processes: concepts for diagnosing programs
Published on December 24, 2025, Byte Lab’s four-part series covers virtual memory, address spaces, processes, registers, stacks, threads, and stack versus heap allocation.
- AI agentsPaper
Layered memory for long-horizon research agents
A post dated April 19, 2026 describes ML-Master 2.0’s Hierarchical Cognitive Caching, with short-, medium-, and long-term memory, and reports a 56.44% medal rate on MLE-Bench after a 24-hour run.
- C and C++Article
Virtual memory and performance in data-intensive systems
Published on May 11, 2026, the article covers page faults, page tables, TLBs, NUMA topology, and Linux internals as tools for analyzing memory behavior and performance.
- C and C++Article
Virtual memory: useful foundations for C and C++ teams
An introductory article published on May 22, 2026, covering paging, address translation, and the role of the MMU in virtual memory.
- AI agentsPaper
MemRL learns to prioritize agent memories at runtime
Published on January 13, 2026, the description presents MemRL, an approach that learns the utility of episodic memories without changing language-model weights.
- Reinforcement learningPaper
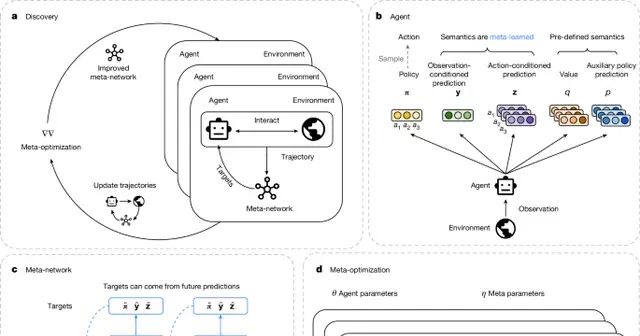
Meta-learning proposes update rules for reinforcement learning
Published on October 24, 2025, the article presents DiscoRL, a method that learns reinforcement learning update rules across agents and environments and reports leading results on benchmarks including Atari and ProcGen.
- Reinforcement learningArticle
RL methods for reasoning models
An article published on March 16, 2026, surveys reinforcement learning methods used with language models and offers engineering teams a starting point for comparison.
- Attention and model architectureProject
microGPT in C explores low-level optimizations
Published on May 3, 2026, the repository presents a dependency-free implementation of microGPT in plain C, using AVX2 intrinsics, fixed-width dot-product kernels, and a fast approximation of the exponential function.
- Speech: TTS and ASRPost
Microsoft describes long-audio transcription with speaker diarization
An article published on March 2, 2026 describes a model that Microsoft says transcribes up to 60 minutes of audio in one pass and supports more than 50 languages.
- Attention and model architecturePaper
MoDA connects attention across LLM layers
Published on April 19, 2026, the paper presents MoDA, a mechanism combining key-value pairs from the current layer with information from earlier layers.
- OCR and document AIModel
OCR model expands document-understanding tasks
In a post published on November 25, 2025, Tencent introduced a document-understanding model with 1 billion parameters for parsing, visual question answering, and translation.
- Attention and model architecturePaper
Masked diffusion models and token order
An ICML 2025 paper examines why masked diffusion models underperform on generation benchmarks and identifies challenges in training with subsets of tokens.
- C and C++Article
Memory models and software concurrency
In an article published on March 1, 2026, Russ Cox introduces hardware memory models as the first topic in a series about memory models.
 arxiv.org
Let's assess your project

I reply with scope and a proposal.