


AI and infrastructure news
- Attention and model architecturePaper
Quiet-STaR: training models to reason before responding
A paper published on September 22, 2026 describes an approach for training language models to generate internal reasoning before visible text, based on the idea that text often contains implicit reasoning.
- Reinforcement learningPaper
Verified reasoning without updating model weights
A post published on June 23, 2026 proposes keeping a language model frozen and retrieving verified reasoning from an external pool, with logical verification as a key challenge.
- RAG and retrievalPaper
Production RAG: evaluating retrieval improvements
A paper published on June 30, 2026, evaluates RAG retrieval strategies and whether their benefits hold across collections with varied formats.
- Training and fine-tuningPost
Local branching to scale LLM inference
A paper published on July 5, 2026 proposes generating and selecting token branches during inference; the post reports better mathematical reasoning than three comparison approaches.
- Attention and model architecturePaper
Tracing training data to LLM circuits
Published on July 7, 2026, the paper presents a method for linking training samples to interpretable units in language models and examines effects on attention heads and in-context learning.
- AI agentsPaper
ReContext: improving evidence use in long contexts
Published on July 6, 2026, the ReContext paper reports improved evidence use across eight 128K datasets, with three model backbones and no training.
- AI agentsPaper
Red Queen Gödel Machine coevolves agents and evaluators
A paper published June 29, 2026 describes a method that evolves agents and evaluators, keeping evaluators fixed per epoch and replacing them only after better performance on reserved ground truth.
- Training and fine-tuningArticle
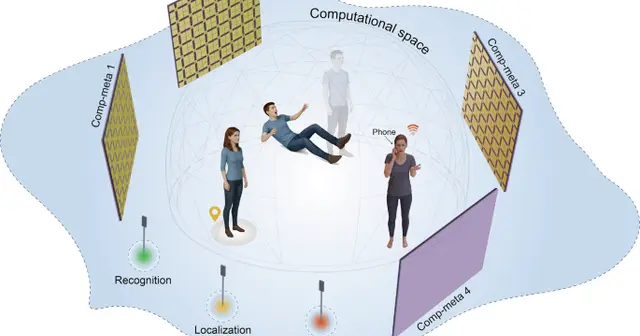
Physical neural network of metasurfaces trained without digital models
The Nature Communications paper describes a physical neural network built from four programmable metasurfaces that learns through electromagnetic interactions to focus waves, recognize objects and perform localization, without digital models.
- C and C++Article
Using C++26 Reflection to Print Class Members
On June 18, 2026, an article by Lieven de Cock demonstrates using C++26 reflection to inspect class members and print their information.
- C and C++Article
C++ reflection can modify private data
An example published by Compiler Explorer on July 23, 2026, uses reflection with an unchecked access context to increment every non-static data member of Foo, including its private field secret.
- Reinforcement learningArticle
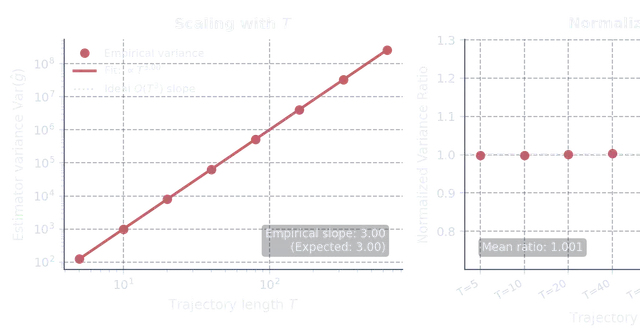
REINFORCE: policy gradients and variance
A post published on July 12, 2026 derives the REINFORCE estimator without differentiating through the environment and analyzes how variance depends on trajectory length.
- AI agentsPaper
Rejection sampling for on-policy LLM alignment
A paper published on July 7, 2026 proposes using rejection sampling to treat accepted off-policy tokens as on-policy and address the variance of accumulated per-token importance sampling ratios.
- SecurityProject
ARM repository offers 29 techniques for exploitation practice
Updated on June 28, 2026, the exploit_me repository provides a vulnerable ARM/AARCH64 application with 29 vulnerability techniques and obvious symbols removed for LLM fine-tuning experiments.
- CUDA and GPU programmingProject
auto-gpu-kernel 1.0 repository generates GPU kernels and harnesses
Published on September 15, 2026, the repository presents a system that evolves GPU kernels and harnesses and won the DSA category of an MLSys 2026 FlashInfer contest.
- Attention and model architecturePaper
RESA: recovering context with sparse attention
Published on September 29, 2026, the RESA paper proposes using residual estimation to recover context ignored by sparse attention, with no additional computational cost, according to the paper.
- Training and fine-tuningPaper
ResidencyRL explores clinical training through simulated consultations
Published on August 10, 2026, the article describes reinforcement learning in simulated clinical environments to train reasoning beyond static medical benchmarks.
- Attention and model architecturePost
Token retention may reduce reliance on the KV cache
A publication dated September 13, 2026, claims that keeping four initial tokens and a 64-token window without training matches or exceeds distilled linear-attention models on nearly all benchmarks.
- Attention and model architecturePaper
RetNet proposes recurrence as an alternative to attention
Published on September 24, 2026, the Retentive Network paper presents a language-model architecture that combines parallel training with recurrent inference.
- RAG and retrievalPaper
In-context retrieval: study tests scale up to one million tokens
A paper published on July 6, 2026, examines language models as retrievers over one-million-token corpora. Its 0.6-billion-parameter BlockSearch generalizes up to 10 times beyond its training length, according to the study.
- RAG and retrievalArticle
Multimodal retrieval with embeddings in a shared space
In a post published on October 6, 2026, Google says EmbeddingGemma 2 represents text, code, images, video, and audio in a shared vector space and uses the Apache 2.0 license.
- SecurityProject
Reversecore_MCP connects AI agents to reverse engineering
The GitHub repository describes an MCP server for AI agents that integrates binary-analysis tools and lists uses in reverse engineering, malware analysis, forensics, vulnerability research, and SAST.
- LLM inferenceProject
Ridgeline: profiling LLM inference with the roofline model
Published on July 8, 2026, the text describes Ridgeline, a PyTorch-based profiler that applies the roofline model to analyze LLM inference workloads.
- SecurityArticle
Riot announces on-demand Vanguard operation
In a post published on June 24, 2026, Riot announced that Vanguard can run only during gameplay when specified device security features are enabled.
- RAG and retrievalProject
ripwire structures repository context for coding agents
Published on September 6, 2026, ripwire is a CLI and MCP server that analyzes 21 languages and returns relevant symbols, relationships, and tests in a token-limited response.
- Training and fine-tuningArticle
Long-horizon RL may favor PPO
A Zhihu post published on June 24, 2026, argues that long, noisy agentic rollouts may make credit assignment harder for GRPO and make PPO's value model useful.
- Training and fine-tuningArticle
RL for beneficial behavior across domains
In a post published on June 18, 2026, OpenAI reports that behavior-focused reinforcement learning improved alignment across domains and resisted adversarial pressure.
- Training and fine-tuningPost
Post-training RL with fewer parameters changed
A post published on July 5, 2026 describes an approach that reinforces high-contribution intermediate layers during post-training RL. It may match or outperform RL across all parameters while changing fewer parameters.
- Training and fine-tuningPaper
RLSD adjusts RLVR updates at the token level
A paper published on July 11, 2026 presents a training method that combines environmental rewards with self-distillation. Across five multimodal reasoning benchmarks, it reports higher average accuracy than the base model and GRPO.
- Training and fine-tuningPaper
RoLA proposes low-rank linear attention for Diffusion Transformers
Published on September 15, 2026, the paper presents RoLA, a method combining low-rank linear attention and rotary position encoding to address scaling bottlenecks in Diffusion Transformers.
- Reinforcement learningPost
RubricEM uses step-by-step criteria to train research agents
Published on July 5, 2026, the work describes agents that create evaluation criteria before researching and reuse lessons from assessed attempts.
- Reinforcement learningProject
RULER turns agent evaluations into rewards for GRPO
A September 17, 2026 post from OpenPipe ART describes how LLM-ranked agent trajectories can produce rewards for agent training.
- Speech: TTS and ASRProject
RVC WebUI: local voice conversion with data
A repository published on September 15, 2026 describes a web interface for training voice-conversion models, including with 10 minutes or less of voice data.
- Attention and model architecturePaper
RWKV combines parallel training with recurrent inference
An article published on September 20, 2026 describes an architecture combining Transformer-style parallel training with RNN-style recurrent inference, with memory and computation scaling linearly with sequence length.
- Attention and model architecturePost
Safety tuning may affect models’ attribution of minds
A study reports that tuning to prevent consciousness claims also reduces the attribution of minds to other entities in three models, and that mechanistic interventions restore these tendencies.
- Training and fine-tuningPost
Sampling for SFT: evaluating post-training
A post published on October 2, 2026 presents a method that adds sampling to the post-training stack and claims it may improve generalization and reduce forgetting in some cases.
- AI agentsPaper
Elastic sandboxes for training and evaluating agents
Published on September 23, 2026, the article describes stateful, elastic execution environments for large-scale agent training and evaluation, as well as defenses against agents exploiting training environments.
- Reinforcement learningPost
Sandbox infrastructure: a scale reference
A publication dated September 22, 2026 reports that a production-scale compute unit spans about 160 nodes and supports more than 380,000 concurrent sandboxes.
- RAG and retrievalPaper
SearchEyes connects simulated worlds to agent training
The SearchEyes paper describes a simulated search world built on a typed knowledge graph for training multimodal agents. Published on July 8, 2026, it addresses gaps among training data, search environments, and reward signals in multi-hop reasoning.
- Attention and model architectureArticle
Sparse attention block selection reduced to O(N log N)
A paper published on September 28, 2026 presents hierarchical block selection with LogSumExp, reducing the cost of this step from O(N²) to O(N log N) for long-context models.
- Reinforcement learningPaper
On-Policy Self-Distillation for Reasoning in LLMs
A paper dated September 28, 2026 describes a training method that combines trajectories generated by the student with dense teacher supervision at each token.
 arxiv.org
Let's assess your project

I reply with scope and a proposal.