


AI and infrastructure news
- Training and fine-tuningArticle
Self-play for pretraining models without natural data
A paper published on September 26, 2026 examines pretraining with program-generated byte sequences and reports transfer to unseen modalities and tasks.
- Training and fine-tuningPost
Data-free self-play: how to evaluate the approach
A paper dated September 25, 2026 explores self-play pretraining without real data and reports predictable reductions in zero-shot validation loss across several modalities.
- AI agentsProject
Semantica: knowledge graphs and agent decision traces
On August 8, 2026, the publication about the open-source Semantica project describes self-hosted infrastructure for turning data into knowledge graphs and recording agent decisions.
- AI agentsPost
Agent serving: measure bottlenecks beyond inference
A paper published on August 21, 2026 presents AgentSysBench, covering 10 agentic applications, and reports that inference is not always the main serving bottleneck.
- LLM inferencePaper
LLM serving: cache and balancing after a year in production
A paper published on August 21, 2026 analyzes a year of production LLM traffic and examines prefix reuse, KV cache locality, and load balancing.
- LLM inferencePost
Serving models across GPU, RAM and NVMe
A September 12, 2026 post reports running a model on an RTX 5090 with 125.7 GiB of RAM and part of the model file on NVMe.
- Training and fine-tuningPaper
SFT in LLMs: tracking effects and deciding when to stop
A paper published on June 15, 2026 examines why supervised fine-tuning can benefit smaller models yet have inconsistent or harmful effects in LLMs.
- RAG and retrievalPaper
SHIFT proposes gates for knowledge conflicts in RAG
Published on June 29, 2026, the paper presents an intervention in FFN activations to balance retrieved evidence and a model’s internal knowledge.
- Training and fine-tuningPost
JEPA SIGReg: concepts and a training loop
Published on July 24, 2026, the guide covers complex numbers, Euler’s formula, the Cramér–Wold theorem, and a functional training loop related to JEPA SIGReg.
- Training and fine-tuningPost
SIGReg and pairwise repulsion in JEPA training
A post dated September 28, 2026 describes how the SIGReg regularizer approximates a sliced MMD and introduces repulsion between batch samples during JEPA training.
- Training and fine-tuningProject
slime: an open framework for LLM post-training
Published on June 19, 2026, the THUDM repository presents a framework for post-training language models with reinforcement learning and scaling.
- Attention and model architecturePaper
Softmax Linear Attention seeks better selection at linear cost
Published on September 16, 2026, the paper proposes applying softmax at the head level to restore global competition in linear attention while retaining linear complexity.
- LLM inferencePaper
Speculative decoding may reduce inference steps
An article dated September 20, 2026 describes a technique that pairs proposals from an efficient model with parallel verification by a larger model to speed generation without changing the output distribution.
- C and C++Article
Spinlocks: reducing context switches without ignoring contention
A September 11, 2026 article on spinlock optimization: keeping threads busy on the CPU can avoid system calls and context switches, but performance trade-offs need evaluation.
- RAG and retrievalPaper
STEB compares style embeddings across 96 datasets
Published on July 1, 2026, the post presents an open-source benchmark evaluating style embeddings across 96 datasets and seven languages.
- LLM inferenceProject
Strata brings local MoE inference to GPUs with 8 GB
On October 1, 2026, the Strata repository page described running the 125-billion-parameter Qwen3.8-Flash-Next MoE model on NVIDIA GPUs with at least 8 GB of VRAM.
- LLM inferencePaper
StreamDQ moves LLM dequantization into HBM memory
A paper published on July 13, 2026 presents an architecture that dequantizes LLM weights in real time on the HBM base die while preserving conventional GPU load semantics.
- AI agentsPost
Survey maps self-improvement in AI agents
Published on July 19, 2026, the survey reviews 239 papers on improving agents through model updates or changes to components such as prompts, memory, and tools.
- LLM inferencePaper
SVD-LLM proposes model compression with post-truncation updates
Published on September 26, 2026, the paper presents an SVD-based LLM compression method that updates compressed weights after truncating singular values.
- Attention and model architecturePost
SwiLA proposes switching between linear attention maps
A paper presented as work at COLM 2026 and dated October 5, 2026 describes an approach that switches among multiple linear maps and highlights the trade-off between expressiveness and memory.
- LLM inferencePaper
Switch Attention dynamically combines full and windowed attention
A paper dated September 16, 2026 presents a dynamic, granular approach to combining full and sliding-window attention in hybrid transformers.
- CUDA and GPU programmingArticle
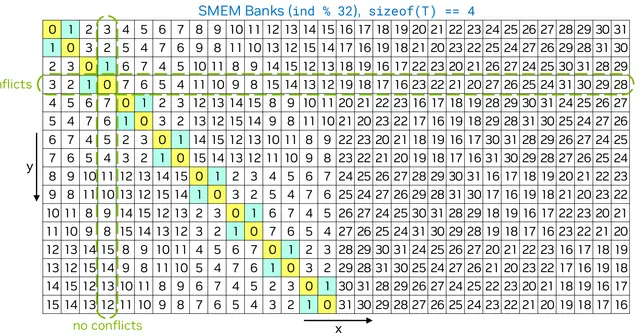
Swizzling to reduce conflicts in CUDA shared memory
A technical article dated August 13, 2026 discusses using swizzling to address bank conflicts in CUDA shared memory, which can affect kernel performance.
- CUDA and GPU programmingProject
Symmetric memory may optimize GPU communication
A Machine Learning Engineering Open Book post, published on October 5, 2026, discusses symmetric memory in NCCL and PyTorch and its potential for small and medium payloads and overlapping communication with computation.
- Training and fine-tuningPaper
TAPA proposes token-aware phase attention for long contexts
Published on June 26, 2026, the paper presents Token-Aware Phase Attention (TAPA), a positional encoding method with a trainable phase function, and compares it with RoPE in long contexts.
- RAG and retrievalProject
Tencent launches WeMM-Embedding multimodal models
On August 26, 2026, Tencent announced a family of embedding models for searching and recommending text, images, and videos. Companies can evaluate multimodal retrieval on their own data.
- Attention and model architecturePaper
Deep learning theory for analyzing model behavior
A book published on June 24, 2026, presents a theoretical framework linking deep neural network architecture and training to model outputs.
- C and C++Article
The Deadlock Empire turns concurrency into a game
Published on September 12, 2026, the text describes a game where participants act as a scheduler and explore flawed programs to learn about concurrency.
- Training and fine-tuningDataset
The Stack v3: a code dataset with 5 trillion tokens
The Stack v3 contains about 5 trillion tokens of code across 713 filtered languages and 224 million repositories, based on GitHub collection completed by August 2025.
- AI agentsPost
ThetaEvolve: test-time learning
Published on July 11, 2026, the open-source ThetaEvolve framework combines in-context learning and test-time reinforcement learning to explore open-ended optimization problems.
- Training and fine-tuningPost
TinyLoRA tests reinforcement fine-tuning with 13 parameters
A post published on September 17, 2026 describes a technique using 13 trainable parameters and reports gains on three mathematics benchmarks.
- LLM inferenceProject
TinyRouter explores routing across open models
A publication dated July 4, 2026 describes a router with about 10,000 parameters and reports benchmark results, while noting that more experiments are needed.
- SecurityPost
Windows tokens and privilege escalation risks
Published on June 27, 2026, the text explains how the Windows kernel’s _TOKEN structure represents identity and security attributes, and how token replacement has historically been used to gain SYSTEM privileges.
- Training and fine-tuningPost
TR-DPO limits deviations in DPO training
A September 21, 2026 publication describes adding a KL-divergence penalty to the DPO loss to limit deviation from the reference model and stabilize offline training.
- SecurityArticle
Tradecraft Garden presents a tool for testing evasion and detection
On June 30, 2026, Tradecraft Garden published a post about Crystal Palace, a linker that transforms and randomizes code, generates YARA rules, and supports reusable tradecraft modules.
- Speech: TTS and ASRPost
Speech transcription: how to evaluate a new model
In an article published on September 3, 2026, Microsoft presents MAI-Transcribe-2, supporting 60 languages, speaker diarization, and word-level timestamps.
- Speech: TTS and ASRDemo
Transcribing one speaker in overlapping speech
A public Space dated September 15, 2026 demonstrates speaker-conditioned transcription: a short audio sample helps isolate the target voice when people speak simultaneously.
- Speech: TTS and ASRPost
Streaming transcription and diarization in one model
A September 3, 2026 post describes a streaming model that combines speech transcription and diarization—identifying who is speaking—in a single model.
- Attention and model architecturePaper
Transformer: from attention to implementation
Chapter 8 of Speech and Language Processing covers Transformer components from intuition to matrix formulation, providing a foundation for assessing how the architecture relates to business applications.
- Attention and model architecturePaper
Transformers: attention and computational costs
An article published on August 2, 2026 explains the mathematical components of Transformers and discusses techniques to reduce attention processing and memory costs.
- Attention and model architecturePaper
Looped Transformers: greater depth without more parameters
An article dated July 17, 2026 examines how looped Transformers reuse blocks to increase unfolded depth and how parameter sharing affects residual scaling.
 arxiv.org
Let's assess your project

I reply with scope and a proposal.